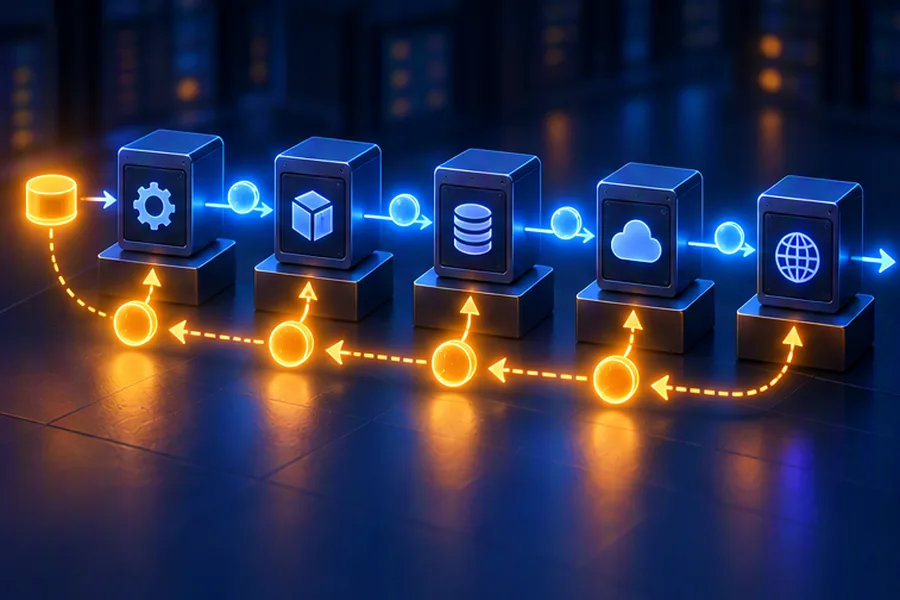
- Once a business operation spans several services, there is no single database transaction to wrap it. Writing to two systems directly (dual writes) eventually leaves them inconsistent.
- Two-phase commit (2PC) gives atomicity across participants but holds locks during voting and blocks if the coordinator dies. Rarely viable across microservices and third-party APIs.
- A saga is a sequence of local transactions with compensating actions for rollback. Orchestration (central coordinator) suits long or critical flows; choreography (events only) suits short ones.
- Make each step reliable with the transactional outbox (business write + event row in one local transaction, relayed later) and idempotent consumers (dedupe by message ID).
- Sagas are ACD without I: intermediate states are visible. Use semantic locks (PENDING states), commutative updates and careful step ordering.
Take a food delivery checkout. Placing one order touches the Order service, the Payment service (which calls a payment gateway), the Restaurant service (which must accept the order), and the Delivery service (which must find a rider). Each owns its own database. If payment succeeds and the restaurant rejects the order, the customer must be refunded. If the server crashes halfway, the system must still end in a sane state. This guide shows how production systems handle that, with code for the parts that are easy to get wrong.
The Problem: No Transaction Spans Two Services
Inside one database, ACID transactions make multi-row changes atomic. Microservices deliberately split data so each service owns its tables, which removes that guarantee for operations that cross service boundaries.
The dual-write problem
The naive approach looks harmless:
def place_order(cmd):
    with db.transaction():
        order = orders.insert(cmd, status="CREATED")
    kafka.publish("order-created", order.to_event())   # what if this fails?
    return order
Every ordering of these two writes has a failure window:
- DB commit succeeds, publish fails (broker down, process crashes): the order exists but no one downstream ever hears about it. It sits in CREATED forever.
- Publish first, then DB commit fails: downstream services charge the customer for an order that does not exist.
- Publish inside the DB transaction: the publish succeeds, then the transaction rolls back. Same as above.
Retries do not fix this, because the process can die between the two writes. You need either a protocol that commits both atomically (2PC) or a design where only one write is authoritative and the other is derived from it reliably (outbox), combined with a way to undo work across services (saga).
Two-Phase Commit (2PC) and Why It Is Rarely Used Across Services
2PC uses a coordinator and several participants (databases or resource managers).
- Prepare phase. The coordinator asks each participant "can you commit?". Each participant does the work, writes it durably to its log, holds its locks, and votes YES or NO. A YES is a promise: "I will commit if told to, even after a crash."
- Commit phase. If all voted YES, the coordinator durably logs COMMIT and tells everyone to commit. If any voted NO or timed out, it tells everyone to abort.
Failure modes
- Coordinator crashes after participants vote YES. Participants are "in doubt": they cannot commit (others may have voted NO) and cannot abort (the coordinator may have decided COMMIT). They hold locks until the coordinator recovers. This is the blocking problem, and it is fundamental to 2PC.
- Participant slow or partitioned. Everyone else waits with locks held. Latency of the whole transaction equals the slowest participant.
- Availability multiplies down. If each of four participants is 99.9% available, the transaction can only proceed when all are up: roughly 99.6%.
- Not supported by most APIs. A payment gateway, an SMS provider, Kafka (outside its own transactions), or another team's REST service will not participate in your XA transaction.
2PC is still used where participants are tightly controlled: XA between a database and a JMS broker in older enterprise Java stacks, and inside distributed databases. Google Spanner and CockroachDB run commit protocols where each participant is itself a consensus-replicated group, so the "coordinator dies" problem is handled by replication rather than blocking. Three-phase commit tries to reduce blocking but assumes bounded network delays, so it is rarely used in practice.
The Saga Pattern: Local Transactions + Compensations
The term comes from Garcia-Molina and Salem's 1987 paper on long-lived transactions. A saga breaks a distributed operation into a sequence of steps T1, T2, ..., Tn. Each step is a local ACID transaction in one service, which commits immediately. For each step there is a compensating transaction C1, C2, ..., Cn that semantically undoes it. If step Ti fails, the saga runs Ci−1, ..., C1 in reverse.
Order checkout as a saga
| Step | Service | Action (Ti) | Compensation (Ci) |
|---|---|---|---|
| 1 | Order | Create order in PENDING | Mark order CANCELLED |
| 2 | Payment | Authorise / capture ₹450 | Void or refund ₹450 |
| 3 | Restaurant | Restaurant accepts order | Notify restaurant of cancellation |
| 4 | Delivery | Assign rider | Release rider |
| 5 | Order | Mark order CONFIRMED | (final step, no compensation) |
If the restaurant rejects in step 3, the saga runs C2 (refund) and C1 (cancel order). The customer sees "Restaurant could not accept your order, refund initiated". No locks were held across services at any point.
Pivot and retriable steps
Chris Richardson's Microservices Patterns introduced a useful classification for ordering steps:
- Compensatable transactions can be undone (create pending order, reserve inventory).
- The pivot transaction is the go/no-go point. If it succeeds, the saga will run to completion.
- Retriable transactions come after the pivot and are guaranteed to succeed eventually if retried (send confirmation email, update a read model).
Design rule: put steps that are likely to fail and easy to undo first, put the hard-to-undo step (capturing money, shipping a parcel) as the pivot, and make everything after it retriable. Example: reserve inventory and validate the restaurant before capturing payment, so most failures never require a refund.
Orchestration vs Choreography Sagas
Choreography: services react to events
No central coordinator. Each service listens for events and emits its own.
Orchestration: a coordinator drives the steps
A saga orchestrator (often part of the Order service, or a workflow engine) holds the state machine and sends commands to each service, waiting for replies.
| Aspect | Choreography | Orchestration |
|---|---|---|
| Coupling | Services know about each other's events | Services know only their own commands; orchestrator knows the flow |
| Visibility | Flow is implicit, spread across services | Flow is explicit in one place; easy to show status |
| Adding a step | Change several services' subscriptions | Change the orchestrator |
| Cyclic dependencies | Easy to create accidentally | Avoided: services never call each other |
| Single point of failure | None | Orchestrator, mitigated by persisting its state |
| Best for | 2–4 steps, simple reactions | Long, business-critical, or frequently changing flows |
In practice, many teams use workflow engines for orchestration: Temporal (and its predecessor Cadence, created at Uber), AWS Step Functions, Netflix Conductor, or Camunda. They persist the workflow's state after every step, handle retries and timers, and let you write the saga as ordinary code.
An orchestrated saga in code
This framework-free Python sketch shows the essential logic. A workflow engine would persist saga.state durably after each step so it can resume after a crash.
class StepFailed(Exception):
    pass


class CheckoutSaga:
    def __init__(self, order_id, clients, store):
        self.order_id = order_id
        self.c = clients          # order, payment, restaurant, delivery clients
        self.store = store        # durable saga state (DB table)
        self.completed = []       # names of steps that committed

    def run(self):
        steps = [
            ("reserve_order", self.c.order.mark_pending,      self.c.order.cancel),
            ("accept",        self.c.restaurant.accept,       self.c.restaurant.cancel),
            ("charge",        self.c.payment.capture,         self.c.payment.refund),  # pivot
        ]
        try:
            for name, action, _ in steps:
                # idempotency key = saga id + step, so retries are safe
                action(self.order_id, idem_key=f"{self.order_id}:{name}")
                self.completed.append(name)
                self.store.save(self.order_id, completed=self.completed)
        except StepFailed:
            self.compensate(steps)
            return "CANCELLED"

        # after the pivot: retriable steps, retried until they succeed
        self.retry_forever(self.c.delivery.assign_rider)
        self.retry_forever(self.c.order.confirm)
        return "CONFIRMED"

    def compensate(self, steps):
        undo = {name: comp for name, _, comp in steps}
        for name in reversed(self.completed):
            self.retry_forever(undo[name])     # compensations must eventually succeed
        self.store.save(self.order_id, completed=[], status="CANCELLED")

    def retry_forever(self, fn, max_backoff=60):
        import time
        delay = 1
        while True:
            try:
                return fn(self.order_id, idem_key=f"{self.order_id}:{fn.__name__}")
            except Exception:
                time.sleep(delay)
                delay = min(delay * 2, max_backoff)
Note what the sketch makes explicit: every call carries an idempotency key, progress is saved after every step, and compensations retry until they succeed. A real implementation also alerts after a retry budget and parks the saga for manual handling.
Designing Compensating Transactions
A compensation is not a database rollback. Step 2 already committed and other systems may have seen it, so the compensation is a new forward action that semantically reverses the effect.
- Compensations must be idempotent. The orchestrator might send "refund" twice after a timeout.
- Compensations must be retriable until success. A saga stuck halfway through compensation is worse than either end state.
- Some actions cannot be undone. An SMS sent cannot be unsent; a compensating "sorry, your order was cancelled" message is the best you can do. Put such actions after the pivot.
- Compensation may differ from the inverse. Cancelling a flight might incur a fee; refunding a UPI payment is a separate refund transaction with its own ID and timeline, not a reversal of the original.
- Handle the "action timed out" case. If you do not know whether step 2 succeeded, the compensation must be safe to run even if step 2 never happened (refund of a non-existent capture should be a no-op, not an error). Alternatively, query the status first using the idempotency key.
Payment systems are where this matters most; see payment system design for UPI for idempotency keys and reconciliation in detail.
The Transactional Outbox Pattern (with Code)
Every saga step must do two things atomically: change local state and emit an event or reply. The transactional outbox solves the dual-write problem from earlier by making the database the only thing you write to synchronously.
- Write business data and an outbox row in one local transaction. Either both commit or neither does.
- A relay publishes outbox rows to the broker. Either by polling the table or by tailing the database's change log (CDC with Debezium).
- Mark rows published (or delete them) after the broker acknowledges.
CREATE TABLE outbox (
    id            UUID PRIMARY KEY,
    aggregate_id  TEXT        NOT NULL,      -- e.g. order id, used as Kafka key
    event_type    TEXT        NOT NULL,
    payload       JSONB       NOT NULL,
    created_at    TIMESTAMPTZ NOT NULL DEFAULT now(),
    published_at  TIMESTAMPTZ
);
CREATE INDEX outbox_unpublished ON outbox (created_at) WHERE published_at IS NULL;
Writing to the outbox (Python + Postgres)
import json, uuid
import psycopg

def place_order(conn: psycopg.Connection, customer_id: str, items: list, total: int) -> str:
    order_id = str(uuid.uuid4())
    with conn.transaction():
        conn.execute(
            "INSERT INTO orders (id, customer_id, total, status) VALUES (%s, %s, %s, 'PENDING')",
            (order_id, customer_id, total))
        conn.execute(
            "INSERT INTO outbox (id, aggregate_id, event_type, payload) VALUES (%s, %s, %s, %s)",
            (str(uuid.uuid4()), order_id, "OrderCreated",
             json.dumps({"orderId": order_id, "customerId": customer_id,
                         "items": items, "total": total})))
    return order_id   # no broker call here at all
Polling relay
def relay_once(conn, producer, batch=100):
    with conn.transaction():
        rows = conn.execute(
            """SELECT id, aggregate_id, event_type, payload FROM outbox
               WHERE published_at IS NULL
               ORDER BY created_at
               LIMIT %s
               FOR UPDATE SKIP LOCKED""", (batch,)).fetchall()
        for row_id, agg_id, etype, payload in rows:
            producer.produce("orders", key=agg_id,
                             value=json.dumps({"id": str(row_id), "type": etype,
                                               "data": payload}))
        producer.flush()          # wait for broker acks before marking published
        if rows:
            conn.execute("UPDATE outbox SET published_at = now() WHERE id = ANY(%s)",
                         ([r[0] for r in rows],))
If the relay crashes after flush() but before the UPDATE commits, those rows are published again on restart. That is the point: the outbox gives at-least-once delivery, never "lost". FOR UPDATE SKIP LOCKED lets several relay instances run without picking the same rows. Strict per-aggregate ordering with multiple relays needs care (partition relays by aggregate, or use a single relay per partition).
CDC instead of polling
Debezium reads the Postgres WAL or MySQL binlog and publishes outbox inserts to Kafka without polling, with lower latency and no load from repeated queries. Its outbox event router transform routes rows to topics by aggregate_type and uses aggregate_id as the message key. The trade-off is operating Kafka Connect and Debezium. For the broker side, see Kafka vs RabbitMQ vs SQS.
Idempotent Consumers: Handling Duplicate Messages
The outbox, broker retries, consumer group rebalances and orchestrator timeouts all produce duplicates. "Exactly-once" end to end is achieved as at-least-once delivery + idempotent processing.
Pattern: processed-messages table in the same transaction
@Service
public class PaymentEventHandler {
    private final JdbcTemplate jdbc;
    private final PaymentGateway gateway;

    public PaymentEventHandler(JdbcTemplate jdbc, PaymentGateway gateway) {
        this.jdbc = jdbc;
        this.gateway = gateway;
    }

    @Transactional
    public void onOrderCreated(String messageId, OrderCreated evt) {
        // 1. Claim the message id; the primary key makes this atomic.
        int inserted = jdbc.update(
            "INSERT INTO processed_messages (message_id, consumer) VALUES (?, 'payment') " +
            "ON CONFLICT DO NOTHING", messageId);
        if (inserted == 0) {
            return;   // duplicate: already handled, skip safely
        }
        // 2. Local state change in the same transaction.
        jdbc.update("INSERT INTO payments (order_id, amount, status) VALUES (?, ?, 'PENDING')",
                    evt.orderId(), evt.total());
        // 3. Outbox row for the reply, same transaction again.
        jdbc.update("INSERT INTO outbox (id, aggregate_id, event_type, payload) " +
                    "VALUES (gen_random_uuid(), ?, 'PaymentRequested', ?::jsonb)",
                    evt.orderId(), "{\"orderId\":\"" + evt.orderId() + "\"}");
    }
}
If the transaction rolls back, the message ID claim rolls back too, so a redelivery will be processed. If it commits, any redelivery is skipped. The external gateway call itself happens later in a separate step that passes an idempotency key (for example, the order ID) to the gateway, because the gateway is outside our transaction. Most payment APIs, including Stripe and Razorpay-style APIs, support idempotency keys or receipt IDs for this reason.
Other ways to be idempotent
- Natural idempotency: "set status to SHIPPED" is idempotent; "increment shipped_count" is not.
- Conditional updates:
UPDATE orders SET status='PAID' WHERE id=? AND status='PENDING'; a duplicate affects zero rows. - Unique constraints on business keys: one payment row per order ID.
- Version checks: apply an event only if its sequence number is the next expected one for that aggregate.
Sagas Lack Isolation: Anomalies and Countermeasures
Sagas give you Atomicity (eventually all or nothing, via compensation), Consistency (each service's invariants), and Durability, but not Isolation. Other requests can see and act on intermediate states.
Anomalies you will meet
- Dirty reads: a customer sees "Payment received" for an order that is about to be cancelled because the restaurant rejected it.
- Lost updates: a saga's compensation overwrites a change another saga made in between.
- Acting on uncommitted results: a loyalty service awards points for an order that is later compensated.
Countermeasures
| Countermeasure | How it works | Example |
|---|---|---|
| Semantic lock | Mark records with a *_PENDING state during the saga; other operations check it | Order is APPROVAL_PENDING; cancellation requests wait or are rejected |
| Commutative updates | Design operations so order does not matter | Debit and credit as ledger entries rather than overwriting a balance |
| Pessimistic view | Reorder steps to minimise business risk from dirty reads | Award loyalty points only after the pivot |
| Reread value | Verify a record is unchanged before overwriting (optimistic check) | Compensation checks the version it expects |
| Version file | Record operations as they arrive so they can be reordered | Handle a cancel that arrives before the create |
Timeouts and stuck sagas
Every step needs a timeout. If the restaurant does not respond in 3 minutes, the orchestrator treats it as a rejection and compensates. Run a reconciliation job that finds sagas stuck in non-terminal states for longer than expected and either resumes or escalates them. Workflow engines give you this via durable timers.
How Sagas and Outbox Come Up in Interviews
These patterns show up in system design rounds for e-commerce checkout, payments, ticket booking, ride-hailing and food delivery, and in microservices-focused rounds (see microservices interview questions).
What interviewers probe
- "The payment succeeded but the order service crashed before recording it. What happens?" (Outbox in payment service; payment event is published reliably; order service consumes it idempotently; reconciliation catches anything else.)
- "Why not just use a distributed transaction?" (2PC blocking, availability, external APIs cannot participate.)
- "How do you avoid charging twice?" (Idempotency key per order to the gateway; processed-messages table; unique constraint on payment per order.)
- "Orchestration or choreography here?" (Justify with number of steps and need for visibility.)
- "How does the user see the state while the saga runs?" (PENDING states, polling or push notifications.)
- "What if a compensation fails?" (Retry with backoff, then park for manual handling with alerting.)
A model answer for "design checkout across services"
"I'd model checkout as an orchestrated saga, since it has five steps and we want a status page for support. Steps in order: create order PENDING, reserve inventory, capture payment as the pivot, then confirm and notify, which are retriable. Each service writes its state change and an outbox row in one local transaction; Debezium publishes outbox rows to Kafka keyed by order ID for per-order ordering. Every consumer dedupes by message ID in the same transaction as its writes. The payment step passes the order ID as the gateway's idempotency key. If inventory reservation fails, we only cancel the order; if payment fails, we release inventory and cancel. A reconciliation job compares gateway settlement reports against our payments table daily."
Common mistakes
- Publishing to Kafka right after a DB commit and calling it "event-driven" (dual write).
- Assuming the broker provides exactly-once end to end, so consumers do not dedupe.
- Putting irreversible steps (capturing money, sending emails) first.
- Forgetting timeouts, so sagas hang forever waiting for a reply.
- Designing compensations that fail if the original step never happened.
If your services also store state as events, sagas pair naturally with event sourcing and CQRS. And before reaching for any of this, check whether the operation really needs to span services; sometimes the right fix is a different service boundary, a point we cover in microservices vs monolith.
Frequently Asked Questions
Design Reliable Distributed Systems
Prepflix's system design track covers sagas, outbox, idempotency and payments design with interview-style walkthroughs and mock rounds.
Explore the Prepflix Course →