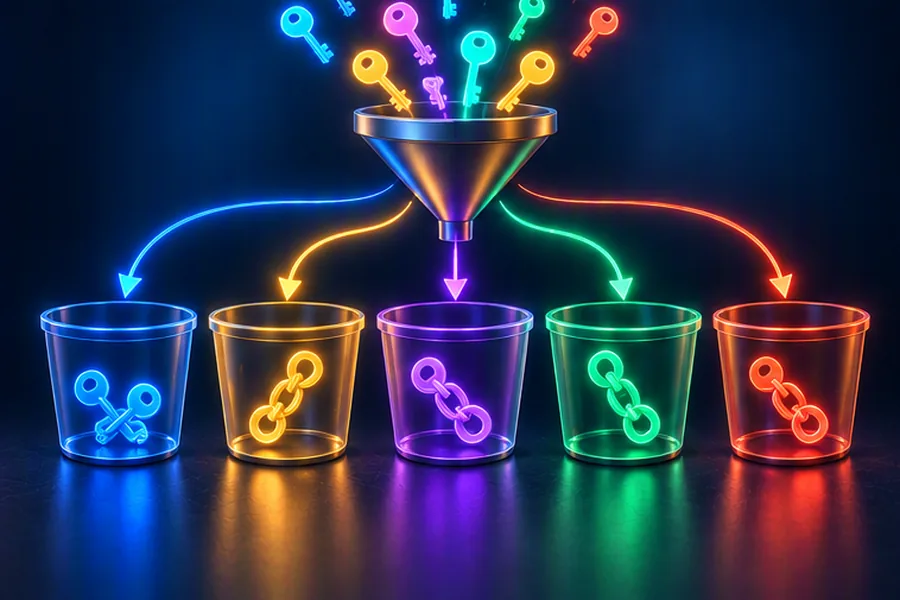
- A hashmap is an array of buckets plus a hash function. Average O(1) operations depend on an even spread of keys and a bounded load factor; the worst case is O(n), or O(log n) for treeified Java buckets.
- Java
HashMap: capacity 16, load factor 0.75, index(n - 1) & hash, chaining that becomes a red-black tree at 8 entries per bucket (if capacity is at least 64), resize by doubling. - Four patterns cover most hashing problems: complement lookup (Two Sum), counting (anagrams, Top K), prefix sum + map (Subarray Sum Equals K) and index/state maps (longest subarray, isomorphism).
- Interviewers probe internals for experienced roles: collisions,
equals/hashCode, mutable keys, concurrency and why capacity is a power of two.
The hashmap is the most valuable data structure in coding interviews. It is the standard way to turn an O(n2) brute force into O(n), and it is the first optimisation interviewers expect you to reach for. It is also one of the most common theory questions for Java developers in India: "how does HashMap work internally?" appears in interviews from service companies to product companies and banks such as Goldman Sachs and JPMorgan.
This guide covers both halves. First, the internals: hashing, buckets, collisions, resizing and the Java-specific details, with a from-scratch implementation. Then the problem patterns, each with code in Java and Python and the exact reasoning that makes the hashmap the right tool.
How a HashMap Works: Hash Function, Buckets and Load Factor
A hashmap stores key-value pairs in an array. To find where a key lives, it:
- Hashes the key into an integer:
h = hash(key). Equal keys must produce equal hashes. - Maps the hash to a bucket index:
index = h mod capacity(or a bitmask when capacity is a power of two). - Resolves collisions: different keys can map to the same bucket, so the bucket holds a small collection (chaining) or the map probes another slot (open addressing).
- Compares keys with equality inside the bucket to find the exact entry.
The load factor is entries divided by buckets. If it grows unbounded, buckets get long and lookups slow down, so the map resizes (typically doubles) when the load factor crosses a threshold and reinserts every entry. A single resize costs O(n), but doubling means the total cost of n inserts is O(n), so each insert is amortised O(1).
Java HashMap Internals: What Interviewers Expect You to Know
Bucket index calculation
static final int hash(Object key) {
    int h;
    return (key == null) ? 0 : (h = key.hashCode()) ^ (h >>> 16);
}
// bucket index for a table of length n (always a power of two):
int index = (n - 1) & hash;
Because the table length is a power of two, (n - 1) & hash keeps only the low bits, which is a cheap replacement for modulo. The XOR with h >>> 16 folds the high bits into the low ones, so hash codes that differ only in their high bits do not all collide in a small table.
Put, step by step
- Lazy allocation. The bucket array is created on the first put (16 buckets by default).
- Empty bucket: place a new node there.
- Occupied bucket: walk the chain; if a node has the same hash and
equalsthe key, replace its value. Otherwise append a new node at the tail (Java 8+; Java 7 inserted at the head, which could create a cycle during concurrent resizes). - Treeify: if the chain length reaches 8 (
TREEIFY_THRESHOLD) and the table has at least 64 buckets (MIN_TREEIFY_CAPACITY), convert the bucket to a red-black tree. If the table is smaller, it resizes instead. A tree shrinks back to a list at 6 entries (UNTREEIFY_THRESHOLD). - Resize: if size exceeds
capacity × loadFactor(12 for the defaults), double the table. Each entry either stays at indexior moves toi + oldCapacity, decided by one bit of its hash, so no rehashing of keys is needed.
Related Java facts worth stating
HashMapallows onenullkey (bucket 0) and null values;HashtableandConcurrentHashMapallow neither.HashMapis not thread-safe.ConcurrentHashMap(Java 8+) uses CAS for empty buckets and locks on the first node of a bucket for updates, so different buckets can be written concurrently.LinkedHashMapadds a doubly linked list for insertion or access order, which makes it a ready-made LRU cache viaremoveEldestEntry.TreeMapis a red-black tree: O(log n) operations but sorted keys and range queries (floorKey,ceilingKey).- If you know the size, presize:
new HashMap<>(expected * 4 / 3 + 1)avoids repeated resizes (Java 19+ addsHashMap.newHashMap(expected)).
For how these collections fit DSA work more broadly, see Java collections for DSA interviews.
Collision Handling: Chaining vs Open Addressing
Collisions are unavoidable: with more possible keys than buckets, the pigeonhole principle guarantees them, and even with few keys the birthday paradox makes them likely (23 keys in 365 buckets already give about a 50% chance of a collision).
| Separate chaining | Open addressing | |
|---|---|---|
| Where colliding keys go | A list or tree hanging off the bucket | Another slot in the same array, found by probing |
| Probing schemes | Not applicable | Linear (i+1, i+2...), quadratic (i+1, i+4...), double hashing (i + k·h2) |
| Load factor | Can exceed 1 (degrades gracefully) | Must stay below 1; performance falls off sharply as it nears 1 |
| Deletion | Simple: unlink the node | Needs tombstones, or probe chains break |
| Cache behaviour | Pointer chasing, less cache-friendly | Contiguous memory, very cache-friendly |
| Used by | Java HashMap, C++ std::unordered_map | Python dict and set, Google's SwissTable (absl::flat_hash_map), Rust HashMap |
Linear probing suffers from primary clustering: runs of occupied slots grow and attract more keys. Quadratic probing and double hashing spread probes out. Python's dict uses a perturbation-based probe sequence and resizes when about two-thirds full; since Python 3.7 it also preserves insertion order, thanks to a compact layout with a separate index array.
unordered_map bucket, turning O(n) into O(n2) and causing a time limit exceeded verdict. The usual defence is a randomised custom hash such as splitmix64 with a time-based seed. In interviews you just mention that worst-case behaviour exists and that hash flooding is a real denial-of-service vector, which is why languages like Python randomise string hashes per process.Implement Your Own HashMap (LeetCode 706 and Beyond)
"Design HashMap" is asked both as a coding question and as an LLD warm-up. A good answer uses chaining, a power-of-two capacity, a load-factor-triggered resize, and handles update-in-place for existing keys.
public class MyHashMap<K, V> {
    private static final class Node<K, V> {
        final K key; V value; Node<K, V> next; final int hash;
        Node(K key, V value, int hash, Node<K, V> next) {
            this.key = key; this.value = value; this.hash = hash; this.next = next;
        }
    }

    private Node<K, V>[] table;
    private int size;
    private static final float LOAD_FACTOR = 0.75f;

    @SuppressWarnings("unchecked")
    public MyHashMap() { table = (Node<K, V>[]) new Node[16]; }

    private static int spread(Object key) {
        int h = (key == null) ? 0 : key.hashCode();
        return h ^ (h >>> 16);
    }
    private int indexFor(int hash, int length) { return hash & (length - 1); }

    public V get(K key) {
        int h = spread(key);
        for (Node<K, V> n = table[indexFor(h, table.length)]; n != null; n = n.next)
            if (n.hash == h && java.util.Objects.equals(n.key, key)) return n.value;
        return null;
    }

    public void put(K key, V value) {
        int h = spread(key);
        int i = indexFor(h, table.length);
        for (Node<K, V> n = table[i]; n != null; n = n.next) {
            if (n.hash == h && java.util.Objects.equals(n.key, key)) { n.value = value; return; }
        }
        table[i] = new Node<>(key, value, h, table[i]);   // head insert is fine single-threaded
        if (++size > table.length * LOAD_FACTOR) resize();
    }

    public boolean remove(K key) {
        int h = spread(key);
        int i = indexFor(h, table.length);
        Node<K, V> prev = null;
        for (Node<K, V> n = table[i]; n != null; prev = n, n = n.next) {
            if (n.hash == h && java.util.Objects.equals(n.key, key)) {
                if (prev == null) table[i] = n.next; else prev.next = n.next;
                size--;
                return true;
            }
        }
        return false;
    }

    @SuppressWarnings("unchecked")
    private void resize() {
        Node<K, V>[] old = table;
        table = (Node<K, V>[]) new Node[old.length * 2];
        for (Node<K, V> head : old) {
            for (Node<K, V> n = head; n != null; ) {
                Node<K, V> next = n.next;
                int j = indexFor(n.hash, table.length);
                n.next = table[j];
                table[j] = n;
                n = next;
            }
        }
    }

    public int size() { return size; }
}
Points to narrate: comparing the cached hash before equals is a cheap filter; Objects.equals handles the null key; resize reuses nodes instead of allocating. Follow-ups you should be ready for: "make it thread-safe" (lock striping per bucket group, or a read-write lock), "what if keys are mutable" (see the next section), and "how would you make worst-case lookups O(log n)" (tree bins, as Java does).
Keys, equals and hashCode: The Contract That Breaks Maps
The contract: if a.equals(b), then a.hashCode() == b.hashCode(). Unequal objects may share a hash code; that is just a collision.
import java.util.*;

final class Point {
    final int x, y;
    Point(int x, int y) { this.x = x; this.y = y; }
    @Override public boolean equals(Object o) {
        if (this == o) return true;
        if (!(o instanceof Point)) return false;
        Point p = (Point) o;
        return x == p.x && y == p.y;
    }
    @Override public int hashCode() { return Objects.hash(x, y); }
}
// Without hashCode(): new HashSet<>(List.of(new Point(1,2))).contains(new Point(1,2)) is (almost always) false.
// A Java record Point(int x, int y) generates both methods correctly.
The mutable key trap
If you put an object in a HashMap and then mutate a field used in hashCode, the entry stays in its old bucket while lookups go to the new one. The entry becomes unreachable through get yet still occupies memory. Rule: use immutable keys (String, boxed numbers, records with immutable fields). In Python this is enforced: lists and dicts are unhashable, so you convert to a tuple or frozenset.
A bad hash function
hashCode() returning a constant is legal but turns the map into a linked list (or tree). A weak combination like x + y collides for (1, 2) and (2, 1). Objects.hash uses the 31-multiplier polynomial, the same idea as String.hashCode.
Pattern 1: Complement Lookup (Two Sum and Friends)
Signal: find a pair (or tuple) satisfying a relation, in unsorted data. For each element, compute what its partner must be and check whether you have already seen it.
public int[] twoSum(int[] nums, int target) {
    Map<Integer, Integer> seen = new HashMap<>();      // value -> index
    for (int i = 0; i < nums.length; i++) {
        Integer j = seen.get(target - nums[i]);
        if (j != null) return new int[]{j, i};
        seen.put(nums[i], i);                           // insert AFTER lookup: no self-pairing
    }
    return new int[0];
}def two_sum(nums, target):
seen = {}
for i, x in enumerate(nums):
if target - x in seen:
return [seen[target - x], i]
seen[x] = i
return []Dry run on [2, 7, 11, 15], target 9: at index 0 we look for 7 (absent) and store 2; at index 1 we look for 2 and find index 0. Answer [0, 1]. One pass, O(n) time and space. Full walkthrough: Two Sum explained.
4Sum II: split the problem in half
Given four arrays, count tuples with a + b + c + d = 0. Brute force is O(n4). Hash all pair sums of A and B (n2 entries), then for each pair of C and D look up -(c + d): O(n2). This "meet in the middle" idea is worth naming.
from collections import Counter

def four_sum_count(A, B, C, D):
    ab = Counter(a + b for a in A for b in B)
    return sum(ab[-(c + d)] for c in C for d in D)
Other members: Contains Duplicate (set membership), Contains Duplicate II (map of value to last index, check distance at most k), Pairs with difference k, and Happy Number (detect a repeated state with a set).
Pattern 2: Counting With Hashmaps (Frequencies and Buckets)
Signal: "most frequent", "appears more than k times", "same multiset of characters", "can be rearranged". Build a frequency map, then reason about counts.
Top K Frequent Elements in O(n) with bucket sort
A heap gives O(n log k). Because a frequency can be at most n, you can bucket elements by frequency and read buckets from high to low for O(n).
from collections import Counter

def top_k_frequent(nums, k):
    freq = Counter(nums)
    buckets = [[] for _ in range(len(nums) + 1)]   # index = frequency
    for value, f in freq.items():
        buckets[f].append(value)
    result = []
    for f in range(len(buckets) - 1, 0, -1):
        for value in buckets[f]:
            result.append(value)
            if len(result) == k:
                return result
return resultpublic int[] topKFrequent(int[] nums, int k) {
Map<Integer, Integer> freq = new HashMap<>();
for (int x : nums) freq.merge(x, 1, Integer::sum);
List<Integer>[] buckets = new List[nums.length + 1];
for (Map.Entry<Integer, Integer> e : freq.entrySet()) {
int f = e.getValue();
if (buckets[f] == null) buckets[f] = new ArrayList<>();
buckets[f].add(e.getKey());
}
int[] res = new int[k];
int idx = 0;
for (int f = nums.length; f > 0 && idx < k; f--)
if (buckets[f] != null)
for (int v : buckets[f]) { if (idx == k) break; res[idx++] = v; }
return res;
}The heap version is covered in heap problems; mention both and their trade-off (the heap is better when k is tiny and data streams in). Group Anagrams uses a frequency signature as a key; it is solved in the string patterns guide. Longest Consecutive Sequence uses a set and only starts counting at sequence starts; see array patterns.
Pattern 3: Prefix Sum + HashMap (Subarray Sum Problems)
This is the hashing pattern most candidates find hardest, and the one product companies ask most in the medium tier. The key identity: the sum of subarray (j, i] equals prefix[i] - prefix[j]. So "a subarray ending at i with sum K exists" is equivalent to "some earlier prefix equals prefix[i] - K", which is a hashmap lookup.
Count subarrays with sum K (LeetCode 560)
public int subarraySum(int[] nums, int k) {
    Map<Integer, Integer> count = new HashMap<>();
    count.put(0, 1);                       // empty prefix
    int prefix = 0, result = 0;
    for (int x : nums) {
        prefix += x;
        result += count.getOrDefault(prefix - k, 0);
        count.merge(prefix, 1, Integer::sum);
    }
    return result;
}
Dry run for nums = [1, -1, 1, 1], k = 2:
| x | prefix | look up prefix - k | found | result | map after |
|---|---|---|---|---|---|
| 1 | 1 | -1 | 0 | 0 | {0:1, 1:1} |
| -1 | 0 | -2 | 0 | 0 | {0:2, 1:1} |
| 1 | 1 | -1 | 0 | 0 | {0:2, 1:2} |
| 1 | 2 | 0 | 2 | 2 | {0:2, 1:2, 2:1} |
The two subarrays are [1, -1, 1, 1] and [1, 1]. Sliding window cannot solve this because of the negative number, which is exactly why the interviewer included one.
Longest subarray with sum K: store the first index
def longest_subarray_sum_k(nums, k):
    first = {0: -1}                  # prefix value -> earliest index
    prefix = best = 0
    for i, x in enumerate(nums):
        prefix += x
        if prefix - k in first:
            best = max(best, i - first[prefix - k])
        if prefix not in first:      # keep the EARLIEST index for maximum length
            first[prefix] = i
    return best
Variants that reuse the same skeleton
- Subarray Sums Divisible by K (974): key on
prefix mod k. In Java, normalise with((p % k) + k) % kbecause%can be negative; Python's%is already non-negative for positive k. - Continuous Subarray Sum (523): remainder map with first index, require length at least 2.
- Contiguous Array (525): treat 0 as -1; the longest subarray with sum 0 has equal 0s and 1s.
- Count submatrices with sum target (1074): fix a pair of rows, compress columns into a 1D array, then run the 1D counting version.
More on the prefix family: prefix sum interview problems.
Pattern 4: Index Maps and State Maps
Signal: you need "where did I last see X?", "what does X map to?", or "have I seen this state before?".
- Last-seen index: Longest Substring Without Repeating Characters jumps the window's left edge using a map of character to last index.
- Bijection checks: Isomorphic Strings and Word Pattern need two maps (forward and backward), otherwise "ab" to "cc" passes incorrectly.
- Object identity maps: Copy List with Random Pointer maps each original node to its clone; Clone Graph does the same for graph nodes. See the linked list guide for the O(1)-space interleaving alternative.
- Value to position for O(1) delete: Insert Delete GetRandom O(1) keeps a list plus a map of value to index; delete swaps the target with the last element and pops.
- Cache structures: LRU cache is a hashmap from key to a node in a doubly linked list.
import random

class RandomizedSet:
    def __init__(self):
        self.vals, self.pos = [], {}

    def insert(self, val):
        if val in self.pos:
            return False
        self.pos[val] = len(self.vals)
        self.vals.append(val)
        return True

    def remove(self, val):
        if val not in self.pos:
            return False
        i, last = self.pos[val], self.vals[-1]
        self.vals[i], self.pos[last] = last, i     # move last element into the hole
        self.vals.pop()
        del self.pos[val]
        return True

    def get_random(self):
        return random.choice(self.vals)
Note the order in remove: update the moved element's position before deleting val, so the case where val is itself the last element still works.
Hashing Practice List
| Pattern | Problems (LeetCode number) |
|---|---|
| Internals | Design HashMap (706), Design HashSet (705) |
| Complement lookup | Two Sum (1), Contains Duplicate (217), Contains Duplicate II (219), 4Sum II (454), Happy Number (202) |
| Counting | Valid Anagram (242), Group Anagrams (49), Top K Frequent Elements (347), Sort Characters by Frequency (451), Longest Consecutive Sequence (128) |
| Prefix + map | Subarray Sum Equals K (560), Contiguous Array (525), Continuous Subarray Sum (523), Subarray Sums Divisible by K (974), Number of Submatrices That Sum to Target (1074) |
| Index/state maps | Isomorphic Strings (205), Word Pattern (290), Insert Delete GetRandom O(1) (380), Copy List with Random Pointer (138), LRU Cache (146) |
HashMap Internals Interview Questions (With Short Answers)
Why is String a good HashMap key?
It is immutable, so its hash cannot change after insertion, and it caches its hash code after the first computation, making repeated lookups cheap.
What is rehashing?
Redistributing all entries into a larger table when the load factor threshold is crossed. In Java 8, each entry either stays at index i or moves to i + oldCapacity, based on one extra bit of its stored hash.
Why treeify at 8 and not earlier?
With a reasonable hash function and load factor 0.75, bucket sizes follow roughly a Poisson distribution, and a chain of 8 is extremely rare. Tree nodes are about twice the size of list nodes, so trees are reserved for the pathological case (bad hash codes or deliberate attacks). The JDK source comments describe this reasoning.
HashMap vs Hashtable vs ConcurrentHashMap vs synchronizedMap?
| Type | Thread-safe | Nulls | Notes |
|---|---|---|---|
HashMap | No | One null key, null values | Default choice in single-threaded code |
Hashtable | Yes, every method synchronised | No | Legacy; avoid |
Collections.synchronizedMap | Yes, one lock | As the wrapped map | Iteration still needs manual locking |
ConcurrentHashMap | Yes, fine-grained | No | Atomic compute/merge; weakly consistent iterators |
What is the time complexity of iterating a HashMap?
O(capacity + size), not O(size): iteration walks every bucket. A map that grew to a large capacity and then had most entries removed iterates slowly, because Java's HashMap never shrinks.
Python dict vs Java HashMap?
Python's dict uses open addressing with a compact, insertion-ordered layout; Java uses chaining with tree bins. Both give average O(1). Python keys must be hashable (immutable built-ins or objects defining __hash__ and __eq__).
How to present a hashing solution in a coding round
- Start from brute force: "For each element I scan the rest: O(n2)."
- Name the repeated work: "The inner scan is a search for one specific value."
- Replace it with a lookup: "A hashmap of what I have seen makes that O(1) on average."
- Say what the map stores and why: value to index, value to count, prefix to first index. Interviewers listen for that sentence.
- Give complexity with the caveat: "O(n) average time, O(n) space; worst case degrades with adversarial collisions."
MyHashMap from memory once, then solve the 20 problems above. If you can explain the dry-run table for Subarray Sum Equals K without notes, hashing is done; move on to linked lists.Frequently Asked Questions
Master Hashing and Every Core DSA Pattern
Prepflix's DSA program covers hashing internals and the problem patterns built on them, with mock interviews that ask the same follow-ups top companies do.
Explore the Prepflix Course →