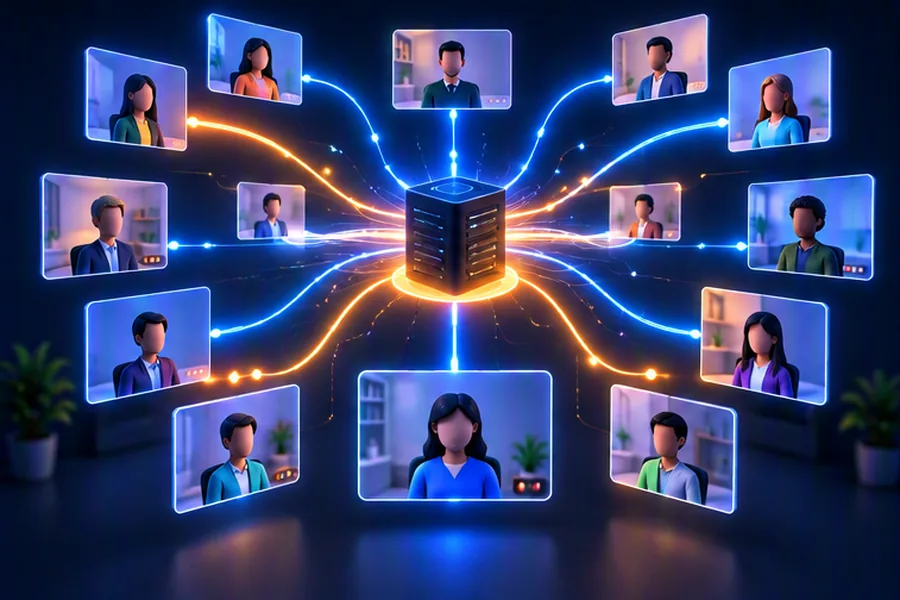
- Split the design into a signaling plane (join, auth, SDP/ICE exchange, roster; WebSocket + stateful room service) and a media plane (RTP over UDP through media servers).
- For group calls use an SFU: each client uploads once, the server forwards without decoding. Mesh breaks after ~4 people; an MCU burns CPU on decode/mix/encode.
- Simulcast (or SVC) lets the SFU send each receiver the layer it can handle: 720p to a fibre laptop, 180p thumbnails to a phone on 4G, with no transcoding.
- STUN/TURN/ICE handle NATs and firewalls; budget TURN relays over TCP/TLS 443 for corporate networks.
- Latency target is about 150 ms one-way, so: UDP, congestion control from receiver feedback, regional media servers, and cascading SFUs for large or global meetings. Recording is a bot participant writing to object storage.
Video conferencing is the system design question where the usual toolkit (load balancer, cache, database) does almost none of the interesting work. The bytes that matter are real-time audio and video packets, they must arrive within a couple of hundred milliseconds, and a late packet is a useless packet. This guide covers the design the way media engineers think about it, with the bandwidth arithmetic that justifies each decision.
Signaling Plane vs Media Plane
The first sentence of your answer should separate the two planes, because they have opposite characteristics:
| Signaling plane | Media plane | |
|---|---|---|
| Carries | Join/leave, auth, SDP offers/answers, ICE candidates, mute state, chat, roster | Encoded audio/video (RTP), feedback (RTCP) |
| Volume | A few KB per participant per minute | Megabits per second per participant |
| Transport | WebSocket / HTTPS (TCP) | UDP (SRTP), fallback TCP/TLS via TURN |
| Loss tolerance | None; must be reliable and ordered | Tolerates loss; retransmits only if it can arrive in time |
| Scaling unit | Rooms (stateful but tiny) | Bandwidth and packets per second on media servers |
Everything else follows: the signaling side looks like a normal real-time web backend; the media side is a fleet of specialised packet routers placed close to users.
Requirements
Functional
- Create/schedule meetings with a link; join from browser, desktop and mobile.
- Audio, video and screen share for up to ~100 interactive participants; webinars with thousands of view-only attendees.
- Gallery and speaker views, active speaker detection, mute/unmute, chat, raise hand.
- Cloud recording; optional live streaming to YouTube-style viewers.
- Waiting room, host controls, meeting passcodes.
Non-functional
- Latency: one-way mouth-to-ear under ~150 ms within a region (ITU-T G.114 guidance), and under ~300 ms globally.
- Resilience to bad networks: calls should survive 5–10% packet loss and bandwidth swings on mobile networks by degrading video before audio.
- Availability: a media server failure should reconnect participants within a few seconds.
- Security: encrypted media (DTLS-SRTP by default), optional end-to-end encryption.
Bandwidth and Capacity Math
Typical bitrates (approximate, they depend on codec, motion and content):
| Stream | Approximate bitrate |
|---|---|
| Audio (Opus, voice) | ~24–40 kbps |
| Video 180p thumbnail | ~100–200 kbps |
| Video 360p | ~400–600 kbps |
| Video 720p | ~1.2–2 Mbps |
| Screen share 1080p (low frame rate) | ~0.5–2.5 Mbps depending on content |
Per meeting: 10 people, gallery view
- Mesh: each person uploads 9 copies at 360p ≈ 9 × 0.5 = 4.5 Mbps upload, and encodes 9 times (or once if the same encoding is reused but then can't adapt per receiver). Indian home broadband uploads are often a fraction of the advertised download speed, and mobile uplinks are worse. Not viable.
- SFU with simulcast: each person uploads 720p + 360p + 180p ≈ 1.5 + 0.5 + 0.15 ≈ 2.15 Mbps (lower layers dropped when bandwidth is short), and downloads 9 tiles at 180p–360p ≈ 2–4 Mbps. The server downloads 10 × 2.15 ≈ 21.5 Mbps and uploads 10 × ~3 Mbps ≈ 30 Mbps.
- MCU: each person uploads ~1.5 Mbps and downloads one mixed 720p stream ~1.5 Mbps. The server decodes 10 streams and encodes 1–10 outputs (one per layout/bitrate). Lowest client bandwidth, highest server cost.
Fleet sizing
Assume a peak of 5 million concurrent participants (a weekday morning when Indian offices and schools overlap with other regions), average downlink 2.5 Mbps and uplink 1.5 Mbps per participant through the SFU:
- SFU egress: 5M × 2.5 Mbps = 12.5 Tbps; ingress 5M × 1.5 Mbps = 7.5 Tbps.
- If a media server with a 10 Gbps NIC is run at ~50% for headroom, it serves 5 Gbps / 2.5 Mbps ≈ 2,000 participants.
- 5M / 2,000 ≈ 2,500 SFU servers, spread across regions, plus spare capacity per region for failover.
- Packet rate matters as much as bits: 2.5 Mbps of ~1,100-byte packets is ~280 packets/s per participant, so ~560,000 packets/s egress per server. That is why SFUs are written in C/C++/Go/Rust with careful use of the kernel network stack.
Signaling is trivial by comparison: 5M connected WebSockets at a few messages per minute. If you want a refresher on structuring these estimates, see back-of-the-envelope estimation.
Mesh vs MCU vs SFU
| Criterion | Mesh | MCU | SFU |
|---|---|---|---|
| Client upload | O(N) | O(1) | O(1) |
| Client download | O(N) | O(1) | O(N) streams, but you choose how many and which layer |
| Server CPU | None | Very high (decode + compose + encode) | Low (packet routing, encryption) |
| Added latency | Lowest | Highest (transcoding adds tens of ms or more) | Low |
| Per-receiver layouts | Yes | Hard; one mix per layout | Yes, client renders |
| End-to-end encryption | Natural | Impossible (server must decode) | Possible (forward without decrypting payload) |
| Best for | 1:1 calls, 3–4 people | Legacy SIP/H.323 room systems, phone dial-in, very weak clients | Almost all modern group calls |
The modern answer is SFU by default, P2P for 1:1 calls when a direct path exists (saves server bandwidth), and an MCU-like mixer only at the edges: PSTN dial-in (phone users need one mixed audio stream), recording and live streaming. Even "SFU" platforms usually mix audio or forward only the top few speakers' audio, since nobody needs 50 audio streams.
WebRTC Building Blocks
WebRTC is the browser standard (and a library used by native apps) that bundles everything a call needs. Know the pieces by name:
- getUserMedia / getDisplayMedia: capture camera, mic, screen.
- RTCPeerConnection: one connection per remote endpoint (with an SFU, typically one connection to the SFU carrying all streams).
- SDP (Session Description Protocol): the offer/answer describing codecs, media tracks, encryption fingerprints and simulcast layers.
- ICE: finds a working network path (next section).
- DTLS-SRTP: keys are negotiated with DTLS, media encrypted with SRTP. Mandatory in WebRTC.
- RTP/RTCP: RTP carries media packets with sequence numbers and timestamps; RTCP carries receiver reports, NACKs (retransmission requests), PLI (picture loss indication: "send me a keyframe") and bandwidth feedback.
- Codecs: Opus for audio (with in-band FEC and DTX); VP8, VP9, H.264 and increasingly AV1 for video. VP9/AV1 support SVC.
- Jitter buffer: receiver-side buffer that reorders packets and smooths timing, adapting its size to network jitter.
STUN, TURN and ICE: Getting Packets Through NATs
Most devices sit behind NAT (home routers, mobile carrier-grade NAT) and often firewalls. A client doesn't even know its public address.
- Gather candidates. The client collects host candidates (local IPs), server-reflexive candidates by asking a STUN server "what IP:port do you see me as?", and relay candidates by allocating a port on a TURN server.
- Exchange candidates through signaling (trickle ICE sends them as they're discovered, so connection setup doesn't wait for all of them).
- Connectivity checks. Both sides send STUN binding requests on candidate pairs and pick the best working pair, preferring direct over relayed.
- Fallback to TURN. If UDP is blocked or the NAT is symmetric, media flows through the TURN relay, ideally over UDP, else TCP, else TLS on port 443, which passes nearly every corporate firewall.
const pc = new RTCPeerConnection({
  iceServers: [
    { urls: "stun:stun.example-meet.com:3478" },
    { urls: ["turn:turn-blr.example-meet.com:3478?transport=udp",
             "turns:turn-blr.example-meet.com:443?transport=tcp"],
      username: "1760100000:user_42",          // time-limited credential
      credential: "base64-hmac-from-signaling" }
  ],
  bundlePolicy: "max-bundle"
});
With an SFU, the server has a public IP, so the client is effectively always the one behind NAT, which simplifies things: the SFU can act as an ICE-lite endpoint, and many deployments let the SFU itself accept TCP/TLS on 443 for blocked clients rather than running separate TURN for server connections. TURN remains essential for P2P 1:1 calls. TURN credentials should be short-lived (an HMAC of an expiry timestamp, the common "TURN REST API" convention) so leaked credentials can't turn your relay into a free proxy.
Signaling Service
WebRTC deliberately doesn't specify signaling. You design it. A minimal protocol over WebSocket:
→ { "type": "join", "meeting_id": "mtg_abc", "token": "jwt...", "caps": {"simulcast": true} }
← { "type": "joined", "participant_id": "p7", "sfu": "wss://sfu-blr-12.example-meet.com",
    "roster": [ {"id": "p1", "name": "Asha", "audio": true, "video": true}, ... ] }
→ { "type": "offer", "sdp": "v=0..." }
← { "type": "answer", "sdp": "v=0..." }
→ { "type": "ice", "candidate": "candidate:1 1 udp 2122260223 10.0.0.5 54400 typ host" }
← { "type": "participant_joined", "participant": {"id": "p9", "name": "Rahul"} }
→ { "type": "layout", "visible": ["p1","p3","p9"], "pinned": "p3", "viewport": "1280x720" }
← { "type": "active_speaker", "id": "p3" }
Architecture of signaling:
- Stateless WebSocket gateways terminate connections (see WebSockets vs SSE vs long polling for why WebSocket fits bidirectional control).
- Room service holds per-meeting state (roster, host, mute states, which SFU hosts it). Shard rooms by
meeting_idwith consistent hashing; all participants' gateways route room messages to the owning instance. Keep a copy in Redis so a crashed room instance can be rebuilt. - Meeting service (plain CRUD + SQL) handles scheduling, links, passcodes and permissions.
- SFU allocator picks a media server for each meeting: nearest region to most participants, with capacity, using live load reports from SFUs.
High-Level Architecture
Simulcast, SVC and Layer Selection
With simulcast, each sender's encoder produces, for example, three independent encodings: h 1280×720 @ 1.5 Mbps, m 640×360 @ 500 kbps, l 320×180 @ 150 kbps. The SFU receives all three and, per receiver, forwards exactly one.
SVC (scalable video coding, VP9/AV1) achieves the same with one layered stream: the SFU drops higher spatial/temporal layers for receivers who can't take them. SVC saves uplink bandwidth and handles switching more smoothly; simulcast has broader codec and hardware support. Mention both; say you'd default to simulcast with VP8/H.264 for compatibility and use SVC where clients support it.
How the SFU decides what each receiver gets
Inputs: the receiver's estimated available bandwidth, its layout (which tiles are visible and at what pixel size), who is the active speaker/pinned, and the sender's currently available layers.
LAYERS = [("h", 1500), ("m", 500), ("l", 150)]   # kbps, best first

def needed_layer(tile_px_height):
    return "h" if tile_px_height >= 540 else "m" if tile_px_height >= 270 else "l"

def allocate(budget_kbps, tiles, audio_kbps=40):
    """tiles: list of (sender_id, tile_px_height, priority), priority 0 = pinned/speaker."""
    budget = budget_kbps - audio_kbps * 3          # forward top-3 speakers' audio
    plan = {}
    order = {"h": 0, "m": 1, "l": 2}
    # pass 1: everyone gets the lowest layer, highest priority first
    for sender, _, _ in sorted(tiles, key=lambda t: t[2]):
        if budget >= 150:
            plan[sender] = "l"; budget -= 150
        else:
            plan[sender] = None                    # video paused, show avatar
    # pass 2: upgrade by priority while budget allows, up to what the tile needs
    for sender, px, _ in sorted(tiles, key=lambda t: t[2]):
        if plan[sender] is None:
            continue
        target = needed_layer(px)
        for name, kbps in reversed(LAYERS):        # l -> m -> h
            if order[name] < order[plan[sender]] and order[name] >= order[target]:
                extra = kbps - dict(LAYERS)[plan[sender]]
                if budget >= extra:
                    budget -= extra; plan[sender] = name
    return plan

print(allocate(2500, [("speaker", 720, 0), ("a", 180, 1), ("b", 180, 1), ("c", 180, 2)]))
# {'speaker': 'h', 'a': 'l', 'b': 'l', 'c': 'l'}
Dry run: budget 2,500 − 120 audio = 2,380. Pass 1 gives all four the 150 kbps layer: 2,380 − 600 = 1,780. Pass 2: the speaker's tile is 720 px, so its target is h; upgrading l → m costs 350 (1,430 left), m → h costs 1,000 (430 left). The thumbnails are 180 px tall, so their target is l and they stay. Result: speaker in HD, thumbnails at 180p, all within 2.5 Mbps. Production allocators (for example in open-source SFUs like mediasoup, Janus, Jitsi Videobridge, LiveKit) are more elaborate but follow the same shape.
Switching layers without glitches
Simulcast layers are independent streams, so the SFU can only switch a receiver to a new layer at a keyframe; it sends a PLI to the sender requesting one. It also rewrites RTP sequence numbers and timestamps so the receiver sees one continuous stream. Upgrades are delayed until a keyframe; downgrades under congestion happen fast.
Bandwidth Adaptation on Unreliable Networks
On an Indian mobile network in a moving car, available bandwidth can swing by several times within seconds. Adaptation happens at both hops:
- Sender → SFU: the sender's congestion controller (in libwebrtc, Google Congestion Control using transport-wide feedback) estimates uplink capacity from packet arrival timing and loss. When it drops, the encoder lowers bitrate, then frame rate, and disables the top simulcast layer.
- SFU → receiver: the SFU runs its own bandwidth estimation per receiver from RTCP feedback and re-runs layer allocation, pausing low-priority video entirely if needed.
- Audio first: audio is small and matters most. Under severe congestion, drop all video before degrading audio. Opus in-band FEC and packet loss concealment cover moderate loss.
- Loss recovery: NACK-based retransmission if RTT is low enough for the retransmit to arrive before playout; forward error correction (FEC) when RTT is high; keyframe requests as last resort (expensive, so rate-limit PLIs).
- Jitter buffer: small (tens of ms) on good networks, grows with jitter. Bigger buffer means fewer glitches but more delay.
Large Meetings, Global Calls and SFU Cascading
Interactive meetings of 100+
- Last-N forwarding: forward video only for the N most recent active speakers plus tiles visible on the receiver's current gallery page; paginate the rest.
- Active speaker detection from the audio-level RTP header extension (RFC 6464), so the SFU doesn't decode audio to know who's talking.
- Audio: forward only the top 3 speakers' audio streams.
Cascading SFUs
Participants in Bengaluru, Singapore and London on one meeting shouldn't all connect to one server in Mumbai. Each joins the nearest SFU, and SFUs cascade: SFU-BLR forwards one copy of each local publisher's stream to SFU-LON over the provider's backbone, which fans out locally. Benefits: shorter last-mile RTT for everyone, and only one cross-continent copy per stream. The room service maintains the SFU tree for each meeting.
Webinars with 10,000+ viewers
Separate interactive panelists (SFU, sub-second) from view-only attendees. For view-only attendees you either fan out through a tree of SFUs (sub-second latency, more cost) or mix to a single stream and push it through HLS/DASH and a CDN (several seconds of latency, very cheap). That second path is the streaming architecture in Hotstar live streaming; promoting an attendee to panelist moves them back to the SFU.
Failure handling
SFUs are stateful (they hold the forwarding state for live streams). If one dies, clients detect ICE disconnection within a few seconds, ask signaling for a new SFU, and re-publish/re-subscribe. The room state lives outside the SFU, so recovery is a reconnection, not data loss. Drain SFUs gracefully during deploys by assigning no new meetings and migrating long-running ones.
Recording and Live Streaming
- Recorder bot joins the meeting as a hidden participant on the SFU, subscribing to the streams it needs (active speaker video, all audio, screen share).
- Composite or not: either run a headless browser/compositor that renders the layout and encodes to MP4 in real time (simple, what users expect), or dump raw RTP per participant and composite later (cheaper in real time, flexible layouts, harder pipeline).
- Write segments to local disk in chunks and upload to object storage continuously, so a recorder crash loses seconds, not the meeting (multipart uploads to storage like in S3-style object storage).
- Post-process asynchronously: transcode to adaptive renditions, generate transcript and summary, thumbnails, then notify the host.
Recording conflicts with end-to-end encryption: if the server can't decrypt, cloud recording must be done by a client. Platforms that offer E2EE typically disable cloud recording in that mode. E2EE on an SFU uses insertable streams / SFrame-style payload encryption: the SFU still reads RTP headers to route, but can't decode the media.
Interview Angle: What Gets You Hired
What interviewers probe
- "Why not P2P?" Do the upload math for 10 people, then say P2P is still used for 1:1.
- "Why not an MCU?" CPU cost, latency, no per-viewer layouts, no E2EE; but mixing is still right for PSTN and recording.
- "A user on 2G joins. What happens?" Congestion control lowers their uplink; SFU sends them 180p or audio-only; their video upload drops to the low layer; others see their thumbnail freeze, not the whole call.
- "How do you choose which SFU?" Geo of first joiner or majority, current load, and cascading when participants are spread out.
- "What's stored in a database?" Very little: meetings, users, permissions, recording metadata. The media path is stateless with respect to the DB.
Common mistakes
- Sending media through the WebSocket/signaling servers or through Kafka.
- Treating the problem like Netflix streaming (CDN, multi-second buffers) for interactive participants.
- Forgetting NAT traversal entirely, or saying "just use STUN" without TURN for restrictive networks.
- No bandwidth math; claiming a 50-person gallery at 720p for everyone.
- Not separating signaling from media, which makes scaling arguments muddy.
A strong 45-minute answer: two planes, SFU with simulcast and the bandwidth math behind it, ICE/TURN, a per-receiver allocation policy, cascading for geography, and recording as a bot. Those six pieces cover the follow-ups interviewers usually reach for.
Frequently Asked Questions
Master Real-Time System Design
Prepflix's system design track covers real-time media, streaming and messaging systems with guided mock interviews.
Explore the Prepflix Course →