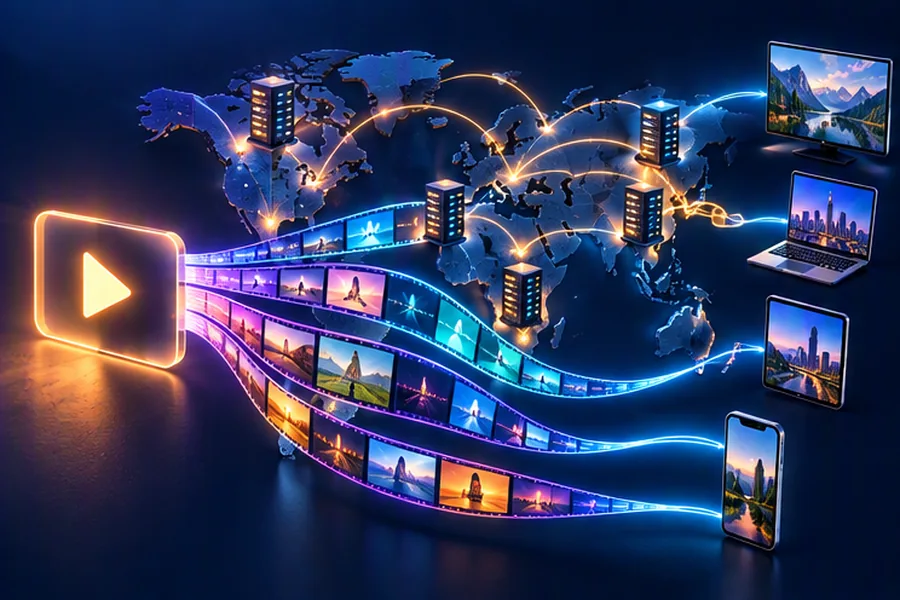
- A video platform is two systems glued by object storage: a write path (resumable upload → transcoding DAG → packaging) and a read path (manifest → CDN segments → adaptive bitrate player).
- Playback dominates: at YouTube-like scale the egress is tens of terabits per second, which is only affordable because 90%+ of bytes are served from CDN edges, not your origin.
- Transcode each upload into a bitrate ladder (240p to 4K), package as short HLS/DASH segments (ideally CMAF so one set of files serves both), and let the player switch renditions every few seconds.
- Parallelise transcoding by splitting the source at GOP boundaries; publish low resolutions first so the video goes live in minutes.
- View counts, likes and watch-time go through an event log and stream aggregation, never a synchronous
UPDATE views = views + 1on a hot row.
"Design YouTube" and "Design Netflix" are the same interview question wearing different clothes. Both ask you to accept huge files from somewhere, convert them into a form every device on earth can play, and deliver those bytes cheaply and smoothly to hundreds of millions of people. The interesting engineering lives in three places: the transcoding pipeline, adaptive bitrate streaming, and the CDN. Everything else (comments, subscriptions, search) is a standard CRUD service you should mention and then deliberately skip.
This guide follows the structure that works in a 45–60 minute round: requirements, numbers, API, data model, architecture, then deep dives on the parts the interviewer actually cares about. If estimation feels shaky, read back-of-the-envelope estimation for system design first; this question leans on it heavily.
Step 1: Clarify Requirements for a Video Streaming Platform
Start by narrowing scope out loud. A good opening: "I will design a YouTube-style platform where creators upload videos and viewers stream them on demand. Live streaming, comments and recommendations are out of scope unless you want them." Live streaming is a different problem (sub-second segment pipelines, no time to do multi-pass encoding); if the interviewer wants that, see Hotstar live streaming for IPL.
Functional requirements
- Users upload videos (up to, say, 12 hours or 256 GB) from web and mobile, with resume on network failure.
- Videos become playable on any device: Android, iOS, smart TVs, browsers, at quality matched to the user's bandwidth.
- Users can view metadata (title, description, thumbnails, view count) and seek anywhere in the video.
- Creators see processing status ("Processing HD…") and basic analytics.
Non-functional requirements
- Playback availability is the top priority (99.99%); upload availability can be lower.
- Low startup latency: first frame in under ~2 seconds; low rebuffering ratio.
- Durability: an uploaded video must never be lost (eleven nines on object storage).
- Cost efficiency: bandwidth and storage dominate the bill, so the design must minimise origin egress.
- Eventual consistency is fine for view counts and likes; a newly uploaded video can take minutes to appear.
Step 2: Capacity Estimation (Show the Math)
These are interview assumptions, not real company figures. State them, round aggressively, and keep moving.
| Assumption | Value |
|---|---|
| Daily active users | 1 billion |
| Videos watched per user per day | 5, average 7 minutes each |
| Hours of video uploaded per minute | 500 |
| Average delivered bitrate | 2.5 Mbps (mix of mobile 480p and TV 1080p) |
| Ladder total bitrate (240p–1080p, one codec) | 0.4 + 0.8 + 1.4 + 2.8 + 5 ≈ 10.4 Mbps |
Read traffic
Views: 1B × 5 = 5B views/day ÷ 86,400 ≈ 58K view starts/sec, peak maybe 3× ≈ 175K/sec. But view starts are not the load; segment requests are. With 4-second segments, a 7-minute view is ~105 segment fetches, so the CDN handles on the order of 6 million segment requests per second on average.
Egress bandwidth
5B views × 420 s × 2.5 Mbps = 5.25 × 1018 bits/day. Divide by 86,400 → ≈ 60 Tbps average, well over 100 Tbps at evening peak. No single data centre serves that. This number alone forces the CDN-first design.
Upload and storage
500 hours/min × 1,440 min = 720,000 hours of new video per day. One hour of the 10.4 Mbps ladder = 3,600 × 10.4 Mb ≈ 37,440 Mb ≈ 4.7 GB. Add a second codec (VP9 or AV1) and 1440p/4K for some fraction, call it ~8 GB per hour of content.
720,000 × 8 GB ≈ 5.8 PB/day of transcoded output, plus the original masters (often kept for re-encoding with future codecs). With erasure coding (~1.5× overhead rather than 3× replication), you are adding roughly 10 PB of raw disk per day, several exabytes per year. This is why cold storage tiering for rarely watched videos matters.
Transcoding compute
If encoding one hour of source into the full ladder costs ~20 CPU-hours (a reasonable order of magnitude for software x264/VP9 at good presets), then 720,000 hours/day needs 14.4M CPU-hours/day ≈ 600,000 cores running constantly. That is why YouTube built custom video transcoding hardware and why the pipeline must be elastic and queue-driven.
Step 3: API Design
Large uploads must be resumable. Never design POST /videos with a 4 GB body; one dropped packet on a mobile network and the user starts over.
POST /v1/uploads
  body: { title, description, size_bytes, content_type, sha256 }
  resp: { upload_id, video_id, upload_url, chunk_size: 8388608 }

PUT  {upload_url}?part=17          # 8 MB chunk, idempotent per part number
  headers: Content-Range: bytes 134217728-142606335/4294967296
  resp: 200 { received_parts: [1..17] }

GET  /v1/uploads/{upload_id}       # which parts arrived? (for resume)
POST /v1/uploads/{upload_id}/complete
  resp: 202 { video_id, status: "PROCESSING" }

GET  /v1/videos/{video_id}
  resp: { title, owner, duration, status, view_count, thumbnails[],
          playback: { hls: "https://cdn.../master.m3u8?sig=...",
                      dash: "https://cdn.../manifest.mpd?sig=..." } }

POST /v1/videos/{video_id}/events  # batched playback heartbeats
  body: [{ type: "start"|"progress"|"rebuffer", pos_ms, rendition, ts }]
Notice that the upload URL can be a pre-signed object-storage URL. The client uploads directly to blob storage and our API servers never touch the bytes. This keeps the upload service stateless and cheap. Playback URLs are also signed with an expiry so hotlinkers cannot embed your CDN.
Step 4: Data Model
Split storage by access pattern: metadata in a sharded database, bytes in object storage, counters in a separate high-write store.
videos              -- sharded by video_id (e.g., MySQL + Vitess)
  video_id      BIGINT PK      -- Snowflake-style ID
  owner_id      BIGINT
  title         VARCHAR(100)
  description   TEXT
  duration_ms   INT
  status        ENUM('UPLOADING','PROCESSING','READY','BLOCKED','DELETED')
  visibility    ENUM('PUBLIC','UNLISTED','PRIVATE')
  master_key    VARCHAR       -- object key of original upload
  created_at    TIMESTAMP

renditions          -- one row per encoded output
  video_id, codec ('h264','vp9','av1'), height, bitrate_kbps,
  segment_prefix, status, PRIMARY KEY (video_id, codec, height)

channel_videos      -- sharded by owner_id for "my uploads" listing
  owner_id, created_at, video_id

video_stats         -- separate counter store (e.g., Bigtable/Cassandra)
  video_id, views, likes, watch_time_sec, updated_at
Why two tables keyed differently for videos? "Get video by id" and "list a channel's videos" have different partition keys. Denormalising into channel_videos avoids scatter-gather across every shard. For sharding trade-offs, see database sharding strategies. The video_id itself should come from a distributed generator such as Snowflake, not an auto-increment column.
Step 5: High-Level Architecture
Walk the interviewer through it in two passes. The write path is asynchronous and event-driven: nothing the user does waits on transcoding. The read path is synchronous only for the tiny metadata call; the heavy bytes go straight from the CDN to the player.
Deep Dive 1: The Resumable Upload Pipeline
Indian mobile networks make this non-optional. A creator in a tier-2 city uploading a 2 GB vlog over 4G will see the connection drop. The protocol has to survive that.
- Initiate. Client calls
POST /v1/uploads. The service creates the video row with statusUPLOADING, starts a multipart upload in object storage, and returns pre-signed URLs (or a single resumable session URI). - Upload chunks. The client sends 8 MB parts, several in parallel. Each part is idempotent by part number, so retries are safe. Each part carries an MD5/CRC so corruption is detected per chunk.
- Resume. After a crash or network switch, the client asks which parts exist and sends only the missing ones.
- Complete. The client calls complete; object storage assembles parts. The service verifies the whole-file hash, flips status to
PROCESSINGand publishes avideo.uploadedevent. - Garbage-collect. Incomplete multipart uploads older than, say, 7 days are aborted by a lifecycle rule so abandoned parts do not cost storage forever.
Two refinements score extra points. First, client-side hashing lets you detect re-uploads of identical files (same SHA-256) and skip transcoding entirely. Second, for very large files you can start probing and even encoding the first chunks before the upload finishes, which shrinks time-to-publish for long videos.
Deep Dive 2: The Transcoding DAG
Transcoding converts the uploaded master (any container, any codec, any frame rate) into a standard set of renditions. Model it as a directed acyclic graph of tasks, not one giant ffmpeg call. A DAG gives you parallelism, per-task retries and the ability to add steps (captions, content ID) without rewriting everything.
Why split at GOP boundaries?
A GOP (group of pictures) starts with an I-frame (keyframe) that can be decoded independently. If you cut the source mid-GOP, the chunk's first frames reference frames that are not in the chunk, and you get corruption. So the splitter cuts at keyframes into chunks of a few seconds each. A 1-hour video becomes ~900 chunks of 4 seconds; with 5 renditions that is 4,500 independent encode tasks you can spread across thousands of workers. Wall-clock time drops from hours to minutes.
Encode with a fixed keyframe interval aligned to the segment duration (for example, a keyframe every 2 seconds, segments of 4 seconds) across all renditions. Aligned keyframes are what let the player switch from 480p to 1080p cleanly at a segment boundary.
Orchestration
Each video gets a workflow instance in an orchestrator (Temporal, AWS Step Functions, or an in-house scheduler; the design of such schedulers is covered in distributed job scheduler design). The orchestrator persists task state, so a worker crash only retries one chunk. Workers pull tasks from priority queues: a creator with 50M subscribers or a premium Netflix title can jump the queue; a backlog of old re-encodes runs on spare capacity at night.
Publish progressively
Do not wait for 4K before marking the video playable. Publish once 360p and 720p are done, write the manifest with what exists, and append higher renditions as they finish. This is why YouTube videos are sometimes briefly available only in SD after upload.
The bitrate ladder
| Rendition | Resolution | Typical H.264 bitrate | Who gets it |
|---|---|---|---|
| 144p/240p | 426×240 | 0.3–0.4 Mbps | 2G/weak 3G, data saver |
| 360p | 640×360 | 0.7–0.8 Mbps | Congested 4G |
| 480p | 854×480 | 1.2–1.5 Mbps | Typical mobile |
| 720p | 1280×720 | 2.5–3 Mbps | Good 4G, laptops |
| 1080p | 1920×1080 | 4.5–6 Mbps | Broadband, TVs |
| 2160p (4K) | 3840×2160 | 15–20 Mbps (less with HEVC/AV1) | Fibre + 4K TV |
Netflix publicly described moving from a fixed ladder to per-title and later shot-based encoding: a cartoon with flat colours looks perfect at a fraction of the bitrate an action movie needs, so the ladder is computed per title. That is affordable for a curated catalogue; for YouTube's long tail, a fixed ladder with a per-video complexity tweak is the pragmatic answer.
Codec choice
H.264 plays everywhere, so it is always encoded. VP9 and AV1 save roughly 30–50% bandwidth at equal quality but cost far more CPU to encode and need device support. The usual strategy: encode H.264 for everything, and add VP9/AV1 only for videos whose views justify the encode cost (for example, after crossing a view threshold). That is a nice "trade compute for bandwidth based on popularity" point to make.
Deep Dive 3: Adaptive Bitrate Streaming with HLS and DASH
Progressive download (one MP4 over HTTP) cannot adapt: if bandwidth drops mid-video, the player stalls. Adaptive bitrate (ABR) streaming fixes this by cutting every rendition into short segments (2–6 seconds) and describing them in a manifest. The player downloads the manifest, then picks which rendition to fetch for each next segment.
#EXTM3U
#EXT-X-VERSION:7
#EXT-X-STREAM-INF:BANDWIDTH=800000,RESOLUTION=640x360,CODECS="avc1.4d401e,mp4a.40.2"
360p/index.m3u8
#EXT-X-STREAM-INF:BANDWIDTH=1400000,RESOLUTION=854x480,CODECS="avc1.4d401f,mp4a.40.2"
480p/index.m3u8
#EXT-X-STREAM-INF:BANDWIDTH=2800000,RESOLUTION=1280x720,CODECS="avc1.4d401f,mp4a.40.2"
720p/index.m3u8
#EXT-X-STREAM-INF:BANDWIDTH=5000000,RESOLUTION=1920x1080,CODECS="avc1.640028,mp4a.40.2"
1080p/index.m3u8#EXTM3U
#EXT-X-VERSION:7
#EXT-X-TARGETDURATION:4
#EXT-X-PLAYLIST-TYPE:VOD
#EXT-X-MAP:URI="init.mp4"
#EXTINF:4.000,
seg_00000.m4s
#EXTINF:4.000,
seg_00001.m4s
...
#EXT-X-ENDLISTHLS vs DASH vs CMAF
| HLS | MPEG-DASH | |
|---|---|---|
| Origin | Apple | ISO/MPEG open standard |
| Manifest | .m3u8 text playlists | .mpd XML |
| Segments | MPEG-TS (legacy) or fMP4 | fMP4 (usually) |
| Native support | iOS/Safari, most smart TVs | Android (ExoPlayer), browsers via MSE |
| DRM | FairPlay | Widevine, PlayReady |
CMAF (Common Media Application Format) standardises fMP4 segments so the same files work for both HLS and DASH. You store media once and emit two small manifests, which halves segment storage and doubles CDN cache efficiency compared with keeping separate TS and fMP4 copies. Mentioning CMAF is a cheap way to sound current. Official spec references: the HLS RFC 8216.
How the player chooses a rendition
Two classic families of ABR algorithms:
- Throughput-based: estimate bandwidth from recent segment download times (with a harmonic mean or EWMA to damp spikes) and pick the highest rendition below, say, 80% of it.
- Buffer-based (e.g., BOLA): when the buffer is low, choose low quality to avoid stalling; when it is full, climb. This handles noisy throughput better.
Production players blend both. A simplified throughput rule:
LADDER_KBPS = [400, 800, 1400, 2800, 5000]   # 240p..1080p

def choose_rendition(recent_kbps, buffer_sec, current_idx):
    # Harmonic mean punishes slow samples, which is what we want
    est = len(recent_kbps) / sum(1.0 / s for s in recent_kbps)
    safe = est * 0.8                          # safety margin
    target = 0
    for i, rate in enumerate(LADDER_KBPS):
        if rate <= safe:
            target = i
    if buffer_sec < 5:                        # panic: drop to lowest
        return 0
    if target > current_idx and buffer_sec < 15:
        return current_idx                    # do not climb on a thin buffer
    if target > current_idx + 1:
        return current_idx + 1                # climb one step at a time
    return target

print(choose_rendition([3000, 3500, 2500], buffer_sec=20, current_idx=2))  # 2
Dry run: the harmonic mean of 3000, 3500 and 2500 kbps is 3 ÷ (1/3000 + 1/3500 + 1/2500) ≈ 2,935 kbps, so the safe estimate is ≈ 2,348 kbps. The highest ladder entry under that is 1400 kbps (index 2); 2800 is too high. The target equals the current index, so the player stays at 480p. Had the samples been 5000, 5500 and 6000 kbps (safe ≈ 4,376), the target would be index 3, and with a 20-second buffer the player would climb to 720p. Being able to trace your own snippet like this is exactly what interviewers probe when you write code in a design round.
Startup latency tricks
- Start at a conservative rendition (or use the bitrate from the user's last session) so the first segment arrives fast.
- Use shorter first segments, prefetch the first segment along with the manifest, and inline the init segment.
- Embed the manifest URL in the video page response so there is no extra round trip.
Deep Dive 4: CDN Strategy
At 60+ Tbps, the CDN is the system. Design it in tiers:
Edge / ISP caches
Servers inside ISPs (Jio, Airtel) or city PoPs. Serve the hottest segments with single-digit-ms latency. Cache hit ratio for popular content is very high.
Regional shield
A mid-tier cache per region that edges miss into. Collapses thousands of edge misses for the same segment into one origin fetch.
Origin
Object storage plus an origin service that signs URLs and handles range requests. Should see only a small fraction of total traffic.
Push vs pull
Pull caching (edge fetches on first miss) suits YouTube's unpredictable long tail. Push/pre-positioning suits Netflix: it knows tomorrow's popular titles, so it fills its Open Connect appliances inside ISP networks during off-peak hours, when transit is cheap. A hybrid is common: pre-warm edges for a video from a huge creator right after publish, pull for everything else.
Long-tail handling
Most uploaded videos get few views. Caching them at every edge wastes space. Serve cold videos from regional or origin tiers, move masters and rarely watched renditions to cheaper storage classes, and even delete high-bitrate renditions of videos with near-zero views (re-encode on demand from the master if they become popular again).
Request routing
DNS-based or anycast routing sends the player to a nearby, healthy, not-overloaded edge. Steering can also be done in the manifest: the playback API returns a CDN hostname chosen for that user's ISP and region, which also allows multi-CDN failover.
Deep Dive 5: View Counts, Likes and Watch Time
A naive UPDATE videos SET views = views + 1 fails twice: a viral video becomes a hot row with tens of thousands of writes per second, and fake views are trivially easy.
- Emit events. The player sends batched heartbeats (start, progress every N seconds, end) to a collection service, which writes them to Kafka partitioned by
video_id. - Validate. A stream job (Flink, Spark Streaming) filters bots and counts a view only after a minimum watch duration, deduplicating by (user or device, video, time window).
- Aggregate. Count per video per 10-second window in memory, then do one increment per window into the counter store. Ten thousand events become one write.
- Serve. The video page reads the counter from cache. It may lag by seconds or minutes, which nobody minds.
- Reconcile. A daily batch job recomputes exact counts from the raw event log in the data lake and corrects drift, and feeds creator analytics and monetisation.
For very hot keys you can also shard the counter (video_id#0 … video_id#15) and sum on read. The same event stream feeds the recommendation system with watch-time signals, which is a good bridge if the interviewer wants to expand scope. The pattern is closely related to ad click aggregation.
YouTube vs Netflix: Same Question, Different Answers
| Dimension | YouTube-style (UGC) | Netflix-style (curated) |
|---|---|---|
| Catalogue | Billions of videos, huge long tail | Thousands of titles |
| Upload volume | Massive, unpredictable | Small, scheduled, studio masters |
| Encoding budget per title | Low; fixed ladder, H.264 first | Very high; per-title/shot-based, many codecs |
| CDN | Pull caching + popularity-based pre-warm | Pre-positioned on ISP appliances off-peak |
| Moderation | Critical: copyright fingerprinting, abuse | Minimal |
| DRM | Only for paid content | Everything |
| Hard problem | Ingest scale + long-tail storage cost | Peak-hour bandwidth + quality per bit |
If the interviewer says "Design Netflix", spend less time on uploads and more on encoding quality, DRM, pre-positioning, and the microservice/API layer for browsing (with resilience patterns like those in circuit breakers and retries). If they say "Design YouTube", ingest, moderation and long-tail economics deserve more airtime. For short vertical video with a scrolling feed, the preloading story changes again; see Instagram Reels design.
Bottlenecks and Trade-offs
- Transcoding backlog during spikes. Autoscale workers on queue depth; prioritise by creator tier; publish low renditions first. Spot/preemptible instances are fine because chunk tasks are idempotent and short.
- Thundering herd on a viral video. Thousands of edges miss the same new segment at once. Request coalescing at the shield tier (one fetch, many waiters) protects origin.
- Metadata hot keys. The video row for a viral video gets read millions of times; cache it in Redis/Memcached with a short TTL, plus a local in-process cache in the API tier. See distributed cache design for stampede protection.
- Storage cost. Erasure coding over replication, storage tiering by access frequency, dropping unused renditions of dead videos.
- Segment length trade-off. Short segments (2 s) adapt faster and start faster but mean more requests, more manifest entries and slightly worse compression. Long segments (6–10 s) are efficient but adapt slowly. 4 seconds is a defensible middle.
What Interviewers Look For (and Common Mistakes)
Signals of a strong answer
- States the read-heavy asymmetry and the bandwidth number, then uses it to justify the CDN and pre-encoding.
- Explains why segments plus manifests enable adaptation, not just that HLS exists.
- Parallelises transcoding with GOP-aligned chunking and knows keyframes must align across renditions.
- Keeps upload bytes off API servers with pre-signed URLs and resumable multipart uploads.
- Treats counters as an aggregation problem.
Common follow-up questions
- "How do you support seeking to minute 47?" Fetch the manifest, compute the segment index (47 × 60 ÷ 4 = segment 705), fetch from there. Thumbnails for the scrub bar come from sprite sheets generated in the DAG.
- "How do you handle a 4K TV on a 3 Mbps line?" ABR caps at whatever throughput allows; device capability caps the top too.
- "A creator deletes a video. What happens?" Soft-delete the row, return 410 from the playback API, purge CDN by URL prefix, and delete storage asynchronously after a retention period.
- "How do you detect copyrighted uploads?" Audio/video fingerprinting stage in the DAG compared against a reference index; it can block, monetise for the rights holder, or flag.
Mistakes I see in mock interviews
A good time budget for 45 minutes: 5 minutes of requirements and numbers, 5 on API and data model, 8 on the architecture diagram, then roughly 25 split across transcoding, ABR and CDN, leaving the last few minutes for bottlenecks. If you can walk that path calmly with the math on the whiteboard, you have given a top-quartile answer to one of the most common questions in system design interviews in India.
Frequently Asked Questions
Crack System Design Rounds
Prepflix's system design track walks you through YouTube, Netflix, Hotstar and 30+ other designs with mock interviews and feedback from engineers who have run these rounds.
Explore the Prepflix Course →