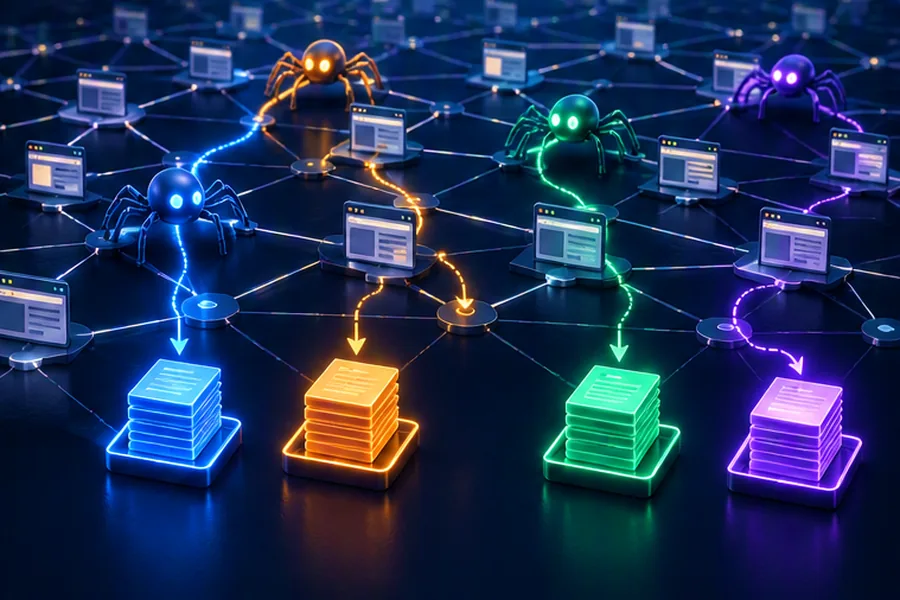
- A crawler loops: pick URL → check robots → resolve DNS → fetch → parse → dedup content → extract links → dedup URLs → add to frontier.
- The URL frontier is two-layered: front queues decide priority, back queues (one per host) enforce politeness via a min-heap of next-allowed fetch times.
- Crawling 5B pages/month ≈ 2,000 pages/s, ~1.5 Gbps, ~100 TB compressed. You need thousands of concurrent fetches (async I/O) spread across thousands of hosts.
- Deduplicate twice: URLs after normalisation (fingerprint set or Bloom filter) and content (exact hash plus simhash for near-duplicates).
- Partition work by host so each host's politeness and robots.txt live on exactly one node; defend against traps with budgets and limits.
"Design a web crawler" is deceptively simple. The core algorithm is a breadth-first search over the web graph, something you have written in a graph interview. What makes it a system design problem is everything BFS ignores: the graph is effectively infinite, the nodes are other people's servers that will block you if you are rude, half the pages are duplicates of the other half, and some sites are designed (deliberately or not) to trap crawlers forever.
This guide designs a search-engine-grade crawler, then dives into the frontier, politeness, robots.txt, DNS and deduplication, which is where interviewers spend their time. The same design applies to narrower crawlers too: a price tracker crawling Flipkart and Amazon listings, a news aggregator, or a training-data crawler for an LLM.
Requirements
Functional
- Given seed URLs, discover and download HTML pages across the web, extracting links to discover more.
- Store fetched content (and metadata: URL, fetch time, status, headers) for downstream indexing.
- Recrawl pages periodically, more often for pages that change often.
- Respect robots.txt and site owners' limits.
Non-functional
- Scale: billions of pages per crawl cycle; horizontally scalable.
- Politeness: never overload any host.
- Robustness: survive malformed HTML, slow servers, infinite URL spaces, and worker crashes without losing frontier state.
- Efficiency: do not re-fetch or re-store duplicates; prioritise important pages.
- Extensibility: new content types (PDF, images) and processors can be plugged in.
Clarify scope: HTML only? JavaScript rendering? One-time crawl or continuous? For this design: HTML first, continuous crawling, JS rendering for a subset as an extension.
Capacity Estimation for Billions of Pages
| Quantity | Math | Result |
|---|---|---|
| Pages per month | Assumption | 5 billion |
| Fetch rate | 5 × 10⁹ ÷ (30 × 86,400 s) | ≈ 1,930 pages/s; plan ~4,000/s peak |
| Average page size | Assumption (HTML only) | ~100 KB |
| Bandwidth | 1,930 × 100 KB | ≈ 193 MB/s ≈ 1.5 Gbps |
| Raw storage per cycle | 5 × 109 × 100 KB | ≈ 500 TB |
| Compressed (~5:1 for HTML) | 500 ÷ 5 | ≈ 100 TB per cycle |
| Discovered URLs | ~10× pages crawled | ~50 billion |
| URL-seen set (exact) | 50B × 8-byte fingerprint | ≈ 400 GB |
| URL-seen set (Bloom, 1% FP) | ~9.6 bits per URL × 50B | ≈ 60 GB |
Concurrency: if an average fetch takes ~1 second (DNS, TCP and TLS handshakes, slow servers), Little's law says in-flight requests = rate × latency = 4,000 × 1 s = 4,000 concurrent fetches at peak. Thread-per-request would need thousands of threads per machine; use asynchronous I/O (epoll-based event loops, Netty, asyncio) so each fetcher machine handles several hundred to a few thousand connections.
Politeness constraint: if each host gets at most one request every ~2 seconds, then 4,000 fetches/s requires at least 8,000 distinct hosts being crawled concurrently. This is the number that shapes the frontier design: you need lots of hosts "ready" at all times, so the frontier must interleave hosts rather than drain one site's URLs at a time.
High-Level Architecture
The Crawl Loop, Step by Step
- Select. The frontier hands a fetcher the next URL whose host is allowed to be contacted now.
- Check robots.txt for that host from cache (fetch it first if missing or older than 24 hours).
- Resolve DNS through the crawler's caching resolver.
- Fetch with timeouts (connect ~5 s, total ~30 s), a size cap (say 10 MB), redirect limits (5 hops), and conditional headers (
If-Modified-Since,If-None-Match) on recrawls so unchanged pages return a cheap 304. - Record status and timing, and feed response time back to politeness (slow host → longer delay).
- Parse HTML leniently, extract text, canonical URL, links, meta robots (
noindex,nofollow). - Content dedup. Exact hash and simhash against the seen-content index; duplicates are recorded as aliases rather than stored again.
- Store the page in append-only WARC files in object storage and its metadata in a key-value store.
- Extract and filter links: resolve relative URLs, normalise, drop disallowed schemes/extensions and trap-like URLs.
- URL dedup against the URL-seen set; new URLs go to the prioritiser.
Deep Dive 1: The URL Frontier (Prioritised BFS)
A single FIFO queue gives you pure BFS, which has two problems. It treats a spam page and a government homepage equally, and because pages link heavily within their own site, consecutive URLs in a FIFO tend to be on the same host, which collides with politeness. The classic solution, from the Mercator crawler design, splits the frontier into two layers.
Front queues: what to crawl next
The prioritiser assigns each URL a priority from 1 to n based on signals such as the linking page's importance (a PageRank-style score), domain authority, estimated change frequency, depth from seeds and whether it appeared in a sitemap. Each priority level has its own FIFO queue. A selector pulls from front queues with a bias toward higher priorities (weighted random), so important pages go first but low-priority pages are not starved.
Back queues: when each host may be contacted
There is one back queue per host currently being crawled, holding only that host's URLs. A min-heap keyed by each back queue's next allowed fetch time tells fetchers which host is ready. A fetcher pops the heap; if the earliest time is in the future it waits; otherwise it takes the head URL of that host's queue, fetches, and pushes the queue back with now + delay. When a back queue empties, it is refilled from the front queues with URLs of a new host.
import java.util.*;

public final class PoliteScheduler {
    private record Ready(long nextAllowedMs, String host) {}

    private final Map<String, ArrayDeque<String>> backQueues = new HashMap<>();
    private final PriorityQueue<Ready> heap =
        new PriorityQueue<>(Comparator.comparingLong(Ready::nextAllowedMs));
    private final Map<String, Long> delayMs = new HashMap<>();   // per-host delay

    public synchronized void add(String host, String url) {
        ArrayDeque<String> q = backQueues.get(host);
        if (q == null) {                                   // new host: ready now
            q = new ArrayDeque<>();
            backQueues.put(host, q);
            heap.add(new Ready(0L, host));
        }
        q.addLast(url);
    }

    /** Returns the next URL that may be fetched now, or null if every host is cooling down. */
    public synchronized String next(long nowMs) {
        Ready r = heap.peek();
        if (r == null || r.nextAllowedMs() > nowMs) return null;
        heap.poll();
        ArrayDeque<String> q = backQueues.get(r.host());
        String url = q.pollFirst();
        if (q.isEmpty()) {
            backQueues.remove(r.host());                   // refill from front queues
        } else {
            long d = delayMs.getOrDefault(r.host(), 2000L);
            heap.add(new Ready(nowMs + d, r.host()));
        }
        return url;
    }

    /** Adaptive politeness: wait ~10x the last response time, min 1 s, max 60 s. */
    public synchronized void recordResponse(String host, long responseMs, int status) {
        long d = Math.max(1000L, Math.min(60_000L, responseMs * 10));
        if (status == 429 || status == 503) d = Math.min(300_000L, d * 4);   // back off hard
        delayMs.put(host, d);
    }

    public static void main(String[] args) {
        PoliteScheduler s = new PoliteScheduler();
        s.add("irctc.co.in", "https://irctc.co.in/a");
        s.add("irctc.co.in", "https://irctc.co.in/b");
        s.add("rbi.org.in", "https://rbi.org.in/x");
        System.out.println(s.next(0));      // https://irctc.co.in/a
        System.out.println(s.next(0));      // https://rbi.org.in/x  (irctc cooling down)
        System.out.println(s.next(0));      // null
        System.out.println(s.next(2000));   // https://irctc.co.in/b
    }
}
Dry run: both hosts start ready at time 0, and the heap orders ties arbitrarily between them, so the first two calls return one URL from each host in some order (the comments show one possible order). After its fetch, irctc.co.in is pushed back with next time 2,000 ms; rbi.org.in's queue empties and is removed. A third call at time 0 finds the heap's head in the future and returns null. At 2,000 ms the irctc host is ready again. One URL per host per delay window, no busy-waiting, O(log H) per operation for H active hosts.
Making the frontier durable
Fifty billion URLs do not fit in memory. Keep only queue heads in memory and spill the rest to disk: each queue is an append-only file or a sorted key range in RocksDB, read in large batches. Checkpoint frontier state regularly so a crashed node resumes rather than rediscovering everything. Some designs use Kafka topics as the durable buffer between link extraction and the frontier; see distributed message queue design.
Deep Dive 2: Politeness Rules
- One connection per host at a time (or a very small number for large sites that explicitly allow more).
- Delay between requests to the same host, adaptive to response time: a server taking 500 ms per page gets a 5-second gap.
- Back off on distress signals: 429, 503, timeouts and connection resets multiply the delay; honour
Retry-After. - Per-IP limits too: thousands of small sites on one shared-hosting IP are, from the server's view, one machine. Group back queues by IP as well as hostname.
- Identify yourself: a User-Agent like
PrepflixBot/1.0 (+https://example.com/bot)with a contact page, so admins can reach you instead of blocking your IP range. - Daily page budgets per host proportional to the site's importance, which also caps damage from traps.
Deep Dive 3: Handling robots.txt
The Robots Exclusion Protocol is now standardised as RFC 9309. Key rules for your design:
- Fetch
/robots.txtper scheme + host + port before crawling the host. Match the most specificUser-agentgroup, falling back to*. - Rule matching: the longest matching
Allow/Disallowpath wins;*and$wildcards are supported. - If robots.txt returns 4xx (e.g., 404), the crawler may access everything. If it is unreachable or 5xx, assume the whole site is disallowed for now.
- Cache it, but per the RFC not for more than 24 hours in normal circumstances.
Crawl-delayis not part of the standard; some crawlers honour it, Google's does not. Treating it as a minimum delay is the polite choice.- Parse at least the first 500 KiB (the RFC sets this as the minimum a crawler must handle).
from urllib import robotparser

rp = robotparser.RobotFileParser()
rp.set_url("https://www.example.com/robots.txt")
rp.read()                                   # fetch and parse

ua = "PrepflixBot"
print(rp.can_fetch(ua, "https://www.example.com/products/123"))
print(rp.crawl_delay(ua))                   # None if not specified
At scale, robots.txt lives in a cache keyed by host (Redis or a local LRU on the node owning that host), with the parsed rule tree stored rather than raw text. Also honour page-level directives: <meta name="robots" content="noindex,nofollow"> and the X-Robots-Tag header.
Deep Dive 4: DNS Resolution and Caching
DNS is the hidden bottleneck. A cold lookup can take tens to hundreds of milliseconds and many standard library resolvers block the calling thread. At 4,000 fetches/s across tens of thousands of hosts, that is unacceptable.
- Run a local caching resolver (for example Unbound) on or near each fetcher node, and use asynchronous DNS clients so lookups do not block the event loop.
- Cache in-process host → IP with TTL respect (and a floor, say 5 minutes, to avoid pathological 0-second TTLs).
- Prefetch: when URLs for a new host enter its back queue, resolve the host before the URL reaches a fetcher.
- Cache negative results (NXDOMAIN) so dead domains discovered in links do not get re-resolved constantly.
Deep Dive 5: URL Normalisation and Dedup
The same page appears under many URLs. Normalise before checking "have I seen this?":
| Raw | Normalised rule |
|---|---|
HTTPS://WWW.Example.com:443/a/./b/../c | Lowercase scheme and host, drop default port, resolve dot segments → https://www.example.com/a/c |
/page#section-2 | Drop fragments |
?utm_source=x&id=5&sessionid=ab12 | Strip tracking and session params; sort remaining → ?id=5 |
%7Euser vs ~user | Decode unreserved percent-encodings |
Page declares rel="canonical" | Record the alias, crawl the canonical |
Then look up a 64-bit fingerprint of the normalised URL in the URL-seen set. At 50 billion URLs, an exact set is ~400 GB, partitioned across nodes by host in RocksDB with an in-memory cache. A Bloom filter cuts that to ~60 GB at 1% false positives; a false positive means you occasionally skip a never-seen URL, which is acceptable for a crawler (you never get false negatives, so you never re-crawl due to the filter). The trade-offs are covered in Bloom filters explained. Many crawlers combine both: Bloom filter in front, exact store behind it for confirmation.
Deep Dive 6: Content Dedup with Simhash
Different URLs often serve the same content: mirrors, syndicated news, print versions, pagination variants. Some studies of large web crawls have found a large share of pages are exact or near duplicates, so dedup is a major saving in storage and indexing.
- Exact duplicates: hash the normalised text (strip whitespace and markup) with a 64-bit or 128-bit hash; check a seen-content store.
- Near-duplicates: the same article with a different timestamp, ad block or "related links" box has a completely different exact hash. Simhash fixes this: similar documents produce fingerprints that differ in only a few bits.
How simhash works
- Split the text into features (words or 3-word shingles) with weights (term frequency).
- Hash each feature to 64 bits.
- Keep a vector V of 64 counters. For each feature and each bit i: add the weight to V[i] if the bit is 1, subtract it if 0.
- The fingerprint's bit i is 1 if V[i] > 0, else 0.
Changing a few features nudges only a few counters across zero, so only a few fingerprint bits flip. Google's 2007 paper "Detecting Near-Duplicates for Web Crawling" (Manku, Jain, Das Sarma) used 64-bit simhash with a threshold of 3 differing bits at the scale of billions of pages.
import hashlib
import re
from collections import Counter

def _h64(token):
    return int.from_bytes(hashlib.blake2b(token.encode(), digest_size=8).digest(), "big")

def simhash(text, ngram=3):
    words = re.findall(r"\w+", text.lower())
    shingles = [" ".join(words[i:i + ngram]) for i in range(max(1, len(words) - ngram + 1))]
    v = [0] * 64
    for shingle, weight in Counter(shingles).items():
        h = _h64(shingle)
        for i in range(64):
            v[i] += weight if (h >> i) & 1 else -weight
    return sum(1 << i for i in range(64) if v[i] > 0)

def hamming(a, b):
    return bin(a ^ b).count("1")

base = ("RBI keeps the repo rate unchanged at its monetary policy meeting, "
        "citing inflation trends and steady growth across sectors this quarter. ") * 4
a = base + "Updated at 10:05 IST."
b = base + "Updated at 10:20 IST. Share this story."
c = "Mumbai Indians win the IPL final in a last-over thriller at Wankhede stadium tonight."
print(hamming(simhash(a), simhash(b)))   # small: near-duplicates
print(hamming(simhash(a), simhash(c)))   # around 32: unrelated
Finding near matches fast. Comparing a new fingerprint against billions is too slow. The paper's trick: split the 64 bits into blocks (for a threshold of 3, e.g., 4 blocks of 16 bits). If two fingerprints differ in at most 3 bits, at least one 16-bit block is identical (pigeonhole). Index fingerprints in tables keyed by each block (or permutations of blocks), look up candidates sharing a block exactly, then check full Hamming distance only for those.
Crawler Traps, JavaScript and Recrawl Scheduling
Traps
- Infinite calendars (
/events?month=2087-04), session IDs in paths, faceted navigation with combinable filters (?color=red&size=m&sort=price&page=9), and symlink loops (/a/b/a/b/a/b/). - Defences: max URL length (~2,000 chars) and path depth, per-host page budgets, detecting repeating path segments, parameter-pattern analysis per host (if 10,000 URLs differ only in one parameter and yield near-duplicate content, stop following that parameter), and content dedup feeding back into the frontier.
JavaScript-heavy pages
Many modern sites render content client-side. Rendering every page in headless Chrome is roughly an order of magnitude more expensive than a plain fetch. Use a two-stage approach: fetch HTML, and if the page looks like an app shell (little text, many scripts), queue it to a separate rendering pool with its own lower throughput budget.
Recrawl scheduling
A news homepage changes every few minutes; an archived 2015 blog post never does. Track change history per URL (content fingerprint per fetch) and estimate change rate; schedule the next crawl at an interval inversely related to change frequency and proportional to the page's importance. Use conditional GETs so unchanged pages cost a 304. Sitemaps with lastmod help too. The scheduler itself is a classic delayed-job system, similar to a distributed job scheduler.
Distributing the Crawler Across Machines
Partition the URL space by host: owner_node = consistent_hash(hostname). Each node owns the back queues, politeness state, robots.txt cache, DNS cache entries and URL-seen shard for its hosts. When a node extracts a link to a host it does not own, it forwards the URL (batched) to the owning node. Benefits: politeness is enforced locally with no cross-node coordination, caches have high hit rates, and URL dedup is a local lookup.
- Load skew: some hosts (Wikipedia, large e-commerce sites) have billions of URLs; their politeness limit caps their throughput anyway, so skew in URL count does not become skew in fetch rate.
- Failure: frontier and seen-sets are checkpointed; on node loss, its host range moves to neighbours (consistent hashing) and they reload state from the last checkpoint. Re-fetching a few pages is fine.
- Geography: fetchers in multiple regions reduce latency to far-away hosts; assign hosts to regions by server location.
- Storage: page content goes to object storage in large WARC files (thousands of pages per file, because billions of tiny objects are inefficient), with a metadata index URL → (file, offset). See object storage design. Downstream consumers (an indexer building an inverted index, a link-graph job computing PageRank) read from there and from a Kafka stream of fetch events.
What Interviewers Look For
- You do the capacity math and derive concurrency (Little's law) and the number of hosts in flight from the politeness delay.
- You explain the two-layer frontier and why a single FIFO fails.
- You treat robots.txt, DNS and dedup as first-class components rather than footnotes.
- You know simhash (or MinHash) for near-duplicates and Bloom filters for URL-seen.
- You partition by host and can explain why.
- You anticipate traps and JavaScript rendering costs.
Typical follow-ups
- "How do you prioritise?" Importance (link-based score), freshness need, sitemap hints, depth.
- "A site asks you to stop." Disallow via robots.txt takes effect within 24 hours; also keep an operator blocklist that applies instantly.
- "How would you crawl only Indian e-commerce product pages?" A focused crawler: seed with target domains, score links by URL patterns and anchor text, and discard off-topic branches early.
Frequently Asked Questions
Prepare for Data-Heavy Design Rounds
Prepflix's system design course covers crawlers, queues, Bloom filters and storage design with structured walkthroughs and mock interviews that push on scale and politeness.
Explore the Prepflix Course →