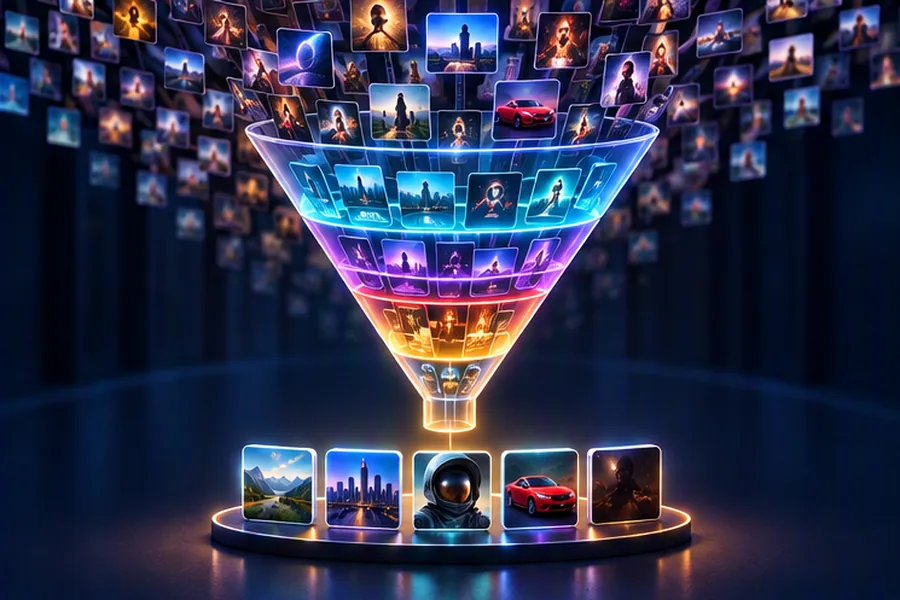
- No production recommender scores the whole catalog. They use a funnel: millions of items → a few thousand candidates (retrieval) → a few hundred scored (ranking) → tens shown (re-ranking).
- Candidate generation mixes sources: two-tower embeddings with ANN search, item-to-item co-occurrence, follows/subscriptions, trending.
- Ranking predicts several engagement probabilities with rich features and combines them into one value score.
- A feature store keeps training and serving features identical; most real-world quality bugs are training-serving skew.
- Prove changes with A/B tests sized correctly; handle cold start with content features and exploration.
Recommendation systems decide most of what you see on Netflix, Amazon, YouTube, Instagram, Flipkart and Swiggy. In interviews the question appears in two flavours: an SDE system design round that wants the serving architecture, data flow and latency budget, and an ML system design round that wants models, labels and metrics. The good news is that both are built on the same skeleton, and if you know that skeleton well you can go deep in whichever direction the interviewer pulls.
I will use "home feed recommendations for a large video or e-commerce app" as the running example, and call out where Netflix-style (long-form, small catalog), Amazon-style (huge catalog, purchase intent) and Instagram-style (fresh UGC, extreme volume) differ.
Scope and Requirements
Start by asking what surface you are building, because "recommendations" can mean a home feed, "because you watched X" rows, "customers also bought", search ranking, or notifications. Pick one and design it well.
Functional
- Given a user and context (time, device, location), return an ordered list of ~50 items for the home feed, paginated.
- Recommendations reflect recent behaviour within minutes, not just yesterday's batch job.
- Support business rules: no out-of-stock products, no already-purchased items, age ratings, region licensing for video.
- Support experimentation: multiple models live at once on different user buckets.
Non-functional
- p99 latency of roughly 150 to 200 ms for the whole recommendation call, since it sits on the critical path of app open.
- High availability with graceful fallback: a degraded but reasonable feed (popular items) beats an empty screen.
- Scales to hundreds of millions of users and tens to hundreds of millions of items.
- Freshness: new items eligible quickly (critical for Instagram/Reels, less for Netflix).
Also clarify the objective. "Maximise clicks" produces clickbait. Netflix-style systems care about long-term retention and satisfaction; e-commerce cares about purchases and returns; social apps balance time spent with creator health. The objective decides labels, and labels decide everything downstream.
Scale Estimates
Illustrative interview numbers for a large consumer app:
- 200M DAU × 20 feed loads/day = 4B recommendation requests/day ≈ 46k QPS average, ~100k QPS peak.
- Catalog: 100M items. 128-dimensional float32 embeddings = 512 bytes each → ~51 GB of item vectors (about half in float16). Fits in RAM across a handful of index shards.
- Ranking 500 candidates per request at 100k QPS = 50M model scorings/s. This is why the ranker must be efficient and why you cannot rank more than a few hundred to a few thousand items per request.
- Interaction events: 200M users × ~200 events/day (impressions, clicks, watches, likes) = 40B events/day, roughly 460k events/s. At ~200 bytes each that is ~8 TB/day of raw logs, the training data source.
The Multi-Stage Funnel
The core idea: use cheap models on many items and expensive models on few items. Each stage reduces the candidate set by one to two orders of magnitude.
Serving architecture
The Recommendation Service is a stateless orchestrator. It fans out to candidate sources in parallel, merges results, fetches features in batch, calls the ranker once with all candidates, applies re-ranking, logs exactly what it showed (with features, for training), and returns.
Candidate Generation (Retrieval)
Retrieval optimises recall: do the good items make it into the candidate set at all? Precision is the ranker's job. Using several sources is standard because each captures a different signal.
Source 1: Two-tower embedding retrieval
A user tower maps user features (history, demographics, context) to a vector u; an item tower maps item features (id, category, text, image embeddings) to a vector v. Training pushes u · v high for items the user engaged with and low for sampled negatives (often in-batch negatives with a correction for popularity). Because the towers are independent, all item vectors are precomputed and loaded into an approximate nearest neighbour (ANN) index such as HNSW or IVF-PQ (FAISS, ScaNN, or a vector database). At request time you run one forward pass of the user tower and query the index for the top 1,000 by inner product. For more on embeddings and vector indexes, see embeddings and semantic search and vector databases compared.
Source 2: Item-to-item co-occurrence
"People who watched/bought X also watched/bought Y" is old (Amazon published item-to-item collaborative filtering in 2003) and still strong. Compute offline, store as item_id → top 200 similar items, and at request time look up the user's last 20 interactions and union their neighbour lists. It is cheap, explainable ("Because you watched…") and hard to beat for e-commerce.
from collections import defaultdict
from itertools import combinations
import heapq
import math

def item_item_neighbors(sessions, k=3):
    """sessions: list of sets of item ids a user engaged with."""
    item_count = defaultdict(int)
    pair_count = defaultdict(int)
    for items in sessions:
        for i in items:
            item_count[i] += 1
        for a, b in combinations(sorted(items), 2):
            pair_count[(a, b)] += 1

    sims = defaultdict(list)
    for (a, b), c in pair_count.items():
        s = c / math.sqrt(item_count[a] * item_count[b])   # cosine on binary vectors
        sims[a].append((s, b))
        sims[b].append((s, a))
    return {i: [b for s, b in heapq.nlargest(k, lst)] for i, lst in sims.items()}

sessions = [{"A", "B", "C"}, {"A", "B"}, {"B", "C", "D"}, {"A", "D"}]
print(item_item_neighbors(sessions)["A"])   # ['B', 'D', 'C']
Dry run for item A: A appears in 3 sessions, B in 3, C in 2, D in 2. Pairs: (A,B)=2, (A,C)=1, (A,D)=1. Similarities: A-B = 2/√9 = 0.667, A-D = 1/√6 = 0.408, A-C = 1/√6 = 0.408. B ranks first; C and D tie, and the tie is broken by item id. Cosine normalisation is what stops a universally popular item from being "similar" to everything. At real scale this runs as a Spark job, with caps on items per session so that one power user with 10,000 interactions does not generate 50M pairs.
Source 3: Social graph and subscriptions
For Instagram-style feeds, recent posts from followed accounts are a primary source. This is the fan-out problem from news feed design: precompute inboxes for most users, pull at read time for celebrity accounts.
Source 4: Trending, popular and fresh
Popular-in-your-region, trending now, and new arrivals. These provide coverage for new users and freshness for everyone. Trending detection itself is a streaming heavy-hitters problem; see top-K trending design.
Merging and filtering
Union the sources with per-source quotas (so one source cannot flood the set), dedupe, then apply hard filters: already purchased, blocked creators, out of stock, not licensed in region, age restrictions. A Bloom filter of "already seen" item ids per user is a common cheap way to filter impressions (Bloom filters explained).
The Ranking Model
The ranker sees each (user, item, context) triple with hundreds of features and predicts what will happen if the item is shown.
Labels: predict several things, combine them
Modern rankers are usually multi-task: one network with shared layers and separate heads for P(click), P(watch > 30 s), expected watch time, P(like), P(share), P(hide/report). The final score is a weighted value model, for example:
score = w1 * P(click) * E[watch_time | click]
      + w2 * P(like)
      + w3 * P(share)
      - w4 * P(hide or report)
The weights are product decisions tuned via A/B tests. This structure lets the business shift objectives (say, more weight on shares) without retraining.
Features
| Group | Examples | Freshness needed |
|---|---|---|
| User profile | Age bucket, country, language, account age, subscription tier | Daily |
| User history | Embedding of last 50 interactions, category affinities, avg watch time | Minutes (streaming) |
| Item | Category, price, duration, creator, content embeddings, age of item | On publish + daily |
| Item engagement | CTR last 1h/24h/7d, like rate, completion rate | Minutes |
| User × item cross | Has user engaged with this creator/category, similarity of item to recent history | Computed at request |
| Context | Time of day, device, network type, position in feed | Request time |
Model choice
Gradient-boosted trees (XGBoost/LightGBM) are a strong, explainable baseline and cheap on CPU. Large platforms use deep models (wide-and-deep, DLRM-style with embedding tables, transformer-based sequence models over user history) because they consume raw ids and sequences well. In an interview, saying "start with GBDT, move to a multi-task DNN once we have the data and infra" is a mature answer.
Position bias
Items at the top get clicked more because they are at the top. If you train naively, the model learns "things we ranked high are good" and reinforces itself. Include position as a feature during training and set it to a fixed value at serving, or train a separate position-bias tower, so the model learns relevance independent of slot.
The Feature Store
The most common way recommenders silently break is training-serving skew: in training, "user's clicks in last 7 days" was computed by a SQL job over the data lake; in serving, it is computed by a different Java service with a slightly different definition. The model is now seeing a distribution it never trained on.
A feature store solves this by defining each feature once and materialising it into two stores:
- Offline store (data lake tables, e.g. Parquet on S3/HDFS, Hive/Iceberg): full history with timestamps, used to build training sets.
- Online store (Redis, Cassandra, DynamoDB): latest value per entity key, read in a few milliseconds at serving.
Point-in-time correctness
When building a training example for an impression at 10:05, you must join feature values as of 10:05, not today's values. Otherwise you leak the future (the item's CTR today includes the click you are trying to predict). Feature stores do this with timestamped "as-of" joins. Even better, many teams log the features used at serving time alongside the impression and train directly on those logs, which removes skew by construction.
Online read path
For one request: 1 user row plus ~500 item rows. Batch the item lookups (multi-get), keep hot item features in a local in-process cache refreshed every minute, and budget ~10 ms. User features can be fetched in parallel with candidate generation.
Offline, Nearline and Online Computation
Netflix popularised the three-tier description, and it is the cleanest way to explain freshness trade-offs.
| Tier | Latency | What runs here | Tools |
|---|---|---|---|
| Offline (batch) | Hours to a day | Model training, item embeddings, co-occurrence tables, ANN index build, long-window aggregates | Spark, Airflow, GPU training clusters |
| Nearline (streaming) | Seconds to minutes | Real-time counters (CTR last hour), user's recent-items list, new item ingestion into indexes | Kafka, Flink, Spark Streaming |
| Online (request) | Milliseconds | User tower inference, ANN lookup, ranking, re-ranking, filters | Model servers, Redis, ANN service |
The rule of thumb: push computation as far offline as freshness allows, because offline compute is cheap and online latency is precious. A user's long-term taste can be a nightly embedding; what they clicked 30 seconds ago must come from the nearline path. The event pipeline is a Kafka-based log; see design Kafka for that piece.
Model deployment
Models are versioned in a registry. A new ranker goes through offline evaluation, then shadow scoring (score live traffic, do not use results), then an A/B test. Two-tower updates are trickier: if you retrain the item tower you must rebuild the ANN index and update the user tower simultaneously, because vectors from different model versions live in different spaces. Version the index with the model.
Re-Ranking: Diversity, Freshness and Business Rules
Sorting purely by predicted score gives a monotonous feed: ten videos from the same creator, five near-identical phones. Re-ranking fixes the list as a whole.
- Diversity: limit items per creator/category in any window of N; or use Maximal Marginal Relevance (below).
- Freshness boosts for new items, especially for UGC platforms.
- Exploration: reserve a small share of slots for items with uncertain scores (bandit-style), which is also how new items escape cold start.
- Business rules: sponsored slots, compliance, promotions, no repeated items across pages.
import numpy as np

def mmr(scores, embeddings, k, lam=0.7):
    """scores: relevance per item (n,), embeddings: L2-normalised (n, d).
    Picks k items balancing relevance and novelty vs already-picked items."""
    n = len(scores)
    selected, remaining = [], list(range(n))
    sim = embeddings @ embeddings.T
    while remaining and len(selected) < k:
        if not selected:
            best = max(remaining, key=lambda i: scores[i])
        else:
            best = max(remaining,
                       key=lambda i: lam * scores[i]
                       - (1 - lam) * max(sim[i][j] for j in selected))
        selected.append(best)
        remaining.remove(best)
    return selected

scores = np.array([0.9, 0.88, 0.5])
emb = np.array([[1.0, 0.0], [1.0, 0.0], [0.0, 1.0]])   # items 0 and 1 are duplicates
print(mmr(scores, emb, 2))   # [0, 2]: the near-duplicate item 1 is skipped
With λ = 0.7, item 1's adjusted score is 0.7 × 0.88 − 0.3 × 1.0 = 0.316, while item 2 gets 0.7 × 0.5 − 0.3 × 0 = 0.35, so the diverse item wins despite a lower raw score. This is O(k·n) per selection step over a few hundred items, cheap enough to run online.
The Cold Start Problem
New users
- Use context you already have: country, language, device, acquisition channel (a user who came from a cricket ad), time of day.
- Onboarding choices: Netflix-style "pick a few titles you like" seed the profile directly.
- Popular and trending within the user's segment as the default candidate source.
- Fast session-based learning: after three or four interactions, a sequence model or simple item-item lookups from those interactions personalise immediately. This is the nearline path earning its keep.
New items
- Content-based embeddings from title, description, image, audio or video so the item tower can place it in vector space with zero interactions.
- Exploration traffic: guarantee each new item a small number of impressions to a matching audience, then let real engagement take over. Short-video platforms are known to use staged distribution of this kind.
- Creator priors: a new video from a creator with strong history starts with a better prior than one from a new account.
New platform (no data at all)
Rules and popularity first, log everything (including what was shown and not clicked), then introduce learned models once you have a few weeks of data. Interviewers like hearing that you would not start with a deep model on day one.
Evaluation and A/B Testing
Offline metrics
| Stage | Metric | Meaning |
|---|---|---|
| Retrieval | Recall@K | Fraction of items the user actually engaged with that appear in the top K candidates |
| Ranking | AUC, log loss | How well predicted probabilities separate positives from negatives, and calibration |
| Ranking (list) | NDCG@K, MAP | Reward putting relevant items at the top of the list |
| Whole list | Coverage, diversity, novelty | Are we recommending the same 1% of the catalog to everyone? |
import math

def ndcg_at_k(relevances, k):
    """relevances: graded relevance of items in the order we ranked them."""
    def dcg(rels):
        return sum((2 ** r - 1) / math.log2(i + 2) for i, r in enumerate(rels[:k]))
    ideal = dcg(sorted(relevances, reverse=True))
    return dcg(relevances) / ideal if ideal > 0 else 0.0

print(round(ndcg_at_k([3, 2, 0, 1], 4), 3))   # 0.993
Offline metrics are necessary but notoriously weak predictors of online impact, because logs only contain feedback on items the old system chose to show. Treat them as a filter for what deserves an A/B test.
Online A/B tests
Assign users (not requests) to buckets by hashing user id with an experiment salt, so a user has a consistent experience. Define one decision metric (watch time per user, orders per user, 7-day retention), plus guardrails (latency, crash rate, diversity, reports, revenue).
Sample size matters. For a proportion metric, a common approximation for 80% power at 5% significance is n ≈ 16 σ² / δ² per arm. With baseline CTR p = 5%, σ² = p(1−p) = 0.0475. To detect a 1% relative lift, δ = 0.0005, so n ≈ 16 × 0.0475 / 0.00000025 ≈ 3 million users per arm. Small lifts need big samples, which is why large platforms can detect effects that smaller companies cannot.
Feedback Loops and Pitfalls
- Popularity feedback loop: popular items get shown, get engagement, get shown more. Counter with exploration, popularity-corrected negative sampling, and coverage metrics.
- Selection bias in training data: you only observe outcomes for items you showed. Log propensities (probability an item was shown) to allow inverse propensity weighting, and keep a small fully-random exploration slice.
- Stale embeddings: an item's vector computed last week does not know it went viral today. Nearline engagement features in the ranker compensate.
- Logging mistakes: if impressions are logged on response rather than on actual display, you train on items users never saw. Log client-side "viewed for at least X ms" events.
- Latency creep: each team adds a feature or a candidate source; p99 drifts upward. Keep a per-stage latency budget and enforce it.
Latency budget
| Stage | Budget (p99) | Fallback if slow |
|---|---|---|
| User features + user tower | 15 ms | Cached user embedding from last session |
| Candidate sources (parallel) | 30 ms | Drop slow sources after timeout |
| Item feature fetch | 15 ms | Local cache, default values |
| Ranking | 50 ms | Lighter model or retrieval scores |
| Re-rank, filters, logging | 10 ms | Simple rules |
| Network and overhead | 30 ms |
If the whole service is down, the client shows a cached last feed or a precomputed popular list from the CDN. Never an empty screen.
Interview Playbook
A 45-minute answer that consistently lands well:
- Clarify surface and objective (3 min). Home feed? Optimise for what? What are the negative signals?
- Numbers (3 min). QPS, catalog size, ranking budget. Conclude that you need a funnel.
- Draw the funnel and serving architecture (8 min). Orchestrator, candidate sources, feature store, ranker, re-ranker, event logging.
- Deep dive retrieval (8 min). Two-tower plus ANN, item-item, merging with quotas.
- Deep dive ranking and features (10 min). Multi-task labels, value model, feature freshness, training-serving skew, position bias.
- Cold start and evaluation (8 min). Exploration, content embeddings, A/B design with guardrails.
- Failure modes and trade-offs (5 min). Fallback feeds, latency budget, feedback loops.
Questions interviewers commonly ask
- "Why not just run the ranking model on all items?" Show the multiplication: 100M items × 100k QPS is impossible; the funnel is a compute-budget decision.
- "How do you pick negatives for the two-tower model?" In-batch negatives plus random negatives, with a log-popularity correction so popular items are not over-penalised.
- "How quickly does a like change the feed?" Through nearline features and the recent-history candidate source: seconds to minutes. Through the embedding: at the next model refresh.
- "How would this differ for Swiggy restaurant recommendations?" Hard constraints dominate (delivery radius, open now, serviceability), context matters more (time of day, weather), and the candidate set per user is small, so retrieval is mostly geo filtering plus ranking. See Swiggy/Zomato design.
For more practice in this style, the AI system design interview guide covers search ranking, fraud detection and ads prediction with the same framework, and the Instagram Reels design shows how a recommender plugs into a video product.
Frequently Asked Questions
Prepare for ML and System Design Rounds
Prepflix's system design program covers recommenders, feeds and ML serving with structured walkthroughs and mock interviews graded like real product-company rounds.
Explore the Prepflix Course →