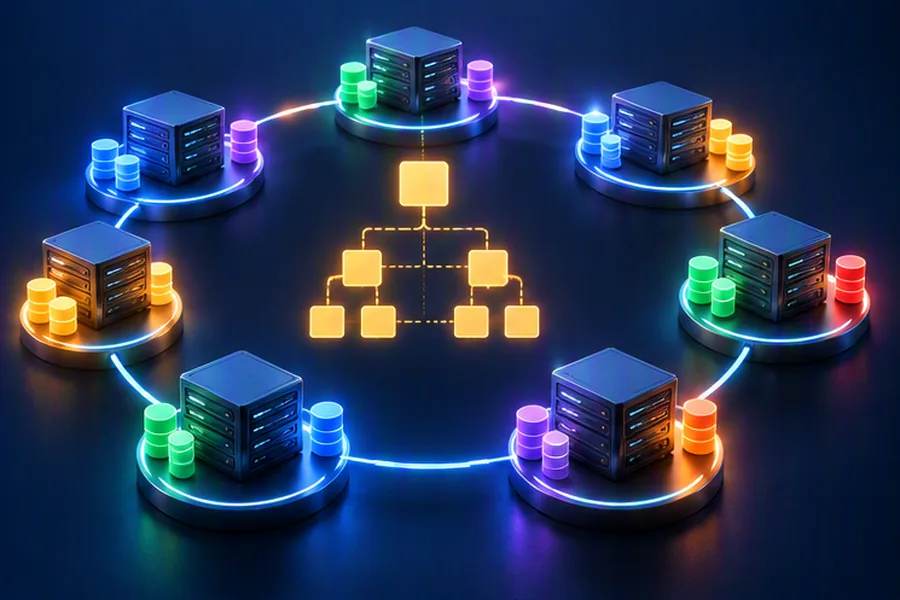
- Partition keys with consistent hashing plus virtual nodes; replicate each key to the next N distinct physical nodes on the ring (the preference list).
- Any node can coordinate a request. A write succeeds after W acks, a read after R replies. With R + W > N the read set and write set overlap.
- Concurrent writes are detected with vector clocks; truly concurrent versions are returned as siblings for the client to merge. LWW is simpler but loses updates.
- Failures are handled in layers: hinted handoff for short outages, read repair for keys that get read, Merkle tree anti-entropy for everything else.
- Membership and failure detection spread by gossip; each node stores data in an LSM tree (WAL, memtable, SSTables, bloom filters, compaction).
"Design a key-value store" is the question where interviewers find out whether you understand distributed systems or have only memorised architectures of famous apps. There is no UI, no feed, no business logic to hide behind. It is just you, a few billion keys, machines that fail, and networks that partition.
The reference design is Amazon's Dynamo paper (DeCandia et al., SOSP 2007), whose ideas live on in Cassandra, Riak and ScyllaDB. This guide builds that design step by step, with the math, dry runs and code you need to explain each mechanism rather than just name it.
Step 1: Requirements
Functional
put(key, value)andget(key), plusdelete(key). Keys up to a few hundred bytes, values up to about 1 MB (typical values are around 1 KB).- Optional per-key TTL.
- No multi-key transactions, joins or secondary indexes. Asking this explicitly is a good move; it scopes the problem.
Non-functional
- Always writable: the classic Dynamo use case was the shopping cart, where rejecting "add to cart" loses money. Prefer availability over strict consistency.
- Tunable consistency per request.
- Low latency: single-digit millisecond p99 reads within a region.
- Horizontal scalability: add nodes without downtime and with minimal data movement.
- Durability: survive the loss of any two nodes, or a whole availability zone, without data loss.
- Decentralised: no single master that becomes a bottleneck or a single point of failure.
Saying "I'll favour availability, so this is an AP system with tunable consistency" frames everything that follows. If the interviewer wants a CP store instead, the design changes to a Raft-replicated one like etcd or TiKV, and you should say so. The reasoning behind this split is covered in the CAP theorem for system design interviews.
Step 2: Capacity Estimation
| Quantity | Assumption / math | Result |
|---|---|---|
| Keys | Given | 10 billion |
| Average key + value + metadata | ~1 KB value + ~100 B key/version/overhead | ~1.1 KB |
| Logical data | 10 × 10⁹ × 1.1 KB | ~11 TB |
| With N = 3 replicas | 11 × 3 | ~33 TB |
| LSM space amplification (~1.3x) + 50% headroom | 33 × 1.3 × 1.5 | ~65 TB raw disk |
| Nodes at 4 TB usable NVMe each | 65 / 4 | ~17, round up to 24 for throughput and zone balance |
| Traffic | Given: 500k reads/s, 100k writes/s at peak | — |
| Replica-level writes | 100k × N(3) | 300k writes/s ≈ 12.5k per node |
| Replica-level reads (R = 2) | 500k × 2 | 1M reads/s ≈ 42k per node |
42k reads per node per second is very achievable when hot data fits in the page cache and bloom filters avoid useless disk reads. The numbers say this is a modest cluster; the difficulty is correctness under failure, not raw scale.
Step 3: API Design
get(key, consistency=QUORUM)
  -> { values: [ {value, context}, ... ] }   // more than one value = concurrent siblings

put(key, value, context=None, consistency=QUORUM, ttl_seconds=None)
  -> ok | error

delete(key, context)   // writes a tombstone, not an immediate removal
The context is an opaque blob containing the vector clock of the version the client read. Passing it back on put tells the store "this new value supersedes what I saw", which is how the store distinguishes an update from a conflicting concurrent write. This read-modify-write contract is the most Dynamo-specific part of the API, so explain it.
Step 4: The Storage Engine on One Node
Before distributing anything, decide how one node stores data. Write-heavy key-value stores almost always use an LSM tree (log-structured merge tree), the same family as RocksDB, LevelDB and Cassandra's engine.
- Write-ahead log. Append the write to a sequential log and fsync (or group-commit) for durability.
- Memtable. Insert into an in-memory sorted structure (skip list or red-black tree). Acknowledge the write.
- Flush. When the memtable reaches, say, 64 MB, write it to disk as an immutable sorted file, an SSTable, and truncate the WAL.
- Read. Check the memtable, then SSTables from newest to oldest. A per-SSTable bloom filter skips files that definitely do not contain the key, and a sparse index finds the block within a file.
- Compaction. Background merges combine SSTables, keep only the newest version of each key and drop tombstones older than a grace period.
Why not a B-tree? B-trees update pages in place, causing random writes; LSM trees turn writes into sequential appends, which suits SSDs and write-heavy workloads. The cost is read amplification and compaction I/O. The full comparison is in B-trees vs LSM trees explained, and the bloom filter trick is unpacked in bloom filters explained.
Step 5: High-Level Architecture
There is no master. Every node runs the same code and knows the ring layout through gossip. A client can be "smart" (it holds the ring and sends directly to a replica) or "dumb" (it hits any node through a load balancer, which forwards). Smart clients save a network hop.
Deep Dive 1: Partitioning with Consistent Hashing
Naive hash(key) mod numNodes remaps almost every key when a node joins or leaves. Consistent hashing places both nodes and keys on a ring of hash values (for example 0 to 264−1). A key belongs to the first node clockwise from its hash. Adding a node moves only the keys between it and its predecessor, about 1/n of the data.
With one position per node, load is lumpy and a failing node dumps its whole range onto a single neighbour. Virtual nodes fix both: each physical node takes many positions (tokens), say 128 to 256. Load evens out statistically, and when a node fails its ranges are spread across many survivors. Heterogeneous hardware is handled by giving bigger machines more tokens.
import bisect
import hashlib


def h(s: str) -> int:
    return int.from_bytes(hashlib.md5(s.encode()).digest()[:8], "big")


class Ring:
    def __init__(self, vnodes: int = 128):
        self.vnodes = vnodes
        self.tokens = []          # sorted token positions
        self.owner = {}           # token -> physical node

    def add_node(self, node: str) -> None:
        for i in range(self.vnodes):
            t = h(f"{node}#{i}")
            bisect.insort(self.tokens, t)
            self.owner[t] = node

    def remove_node(self, node: str) -> None:
        self.tokens = [t for t in self.tokens if self.owner[t] != node]
        self.owner = {t: n for t, n in self.owner.items() if n != node}

    def preference_list(self, key: str, n: int) -> list:
        """First n DISTINCT physical nodes clockwise from hash(key)."""
        if not self.tokens:
            return []
        idx = bisect.bisect(self.tokens, h(key)) % len(self.tokens)
        result = []
        for step in range(len(self.tokens)):
            node = self.owner[self.tokens[(idx + step) % len(self.tokens)]]
            if node not in result:
                result.append(node)
                if len(result) == n:
                    break
        return result


ring = Ring()
for name in ["A", "B", "C", "D", "E"]:
    ring.add_node(name)
print(ring.preference_list("cart:user42", 3)) # e.g. ['D', 'A', 'C']import java.nio.charset.StandardCharsets;
import java.security.MessageDigest;
import java.util.*;
public class Ring {
private final TreeMap<Long, String> ring = new TreeMap<>();
private final int vnodes;
public Ring(int vnodes) { this.vnodes = vnodes; }
static long hash(String s) {
try {
byte[] d = MessageDigest.getInstance("MD5").digest(s.getBytes(StandardCharsets.UTF_8));
long v = 0;
for (int i = 0; i < 8; i++) v = (v << 8) | (d[i] & 0xff);
return v;
} catch (Exception e) { throw new RuntimeException(e); }
}
public void addNode(String node) {
for (int i = 0; i < vnodes; i++) ring.put(hash(node + "#" + i), node);
}
public void removeNode(String node) {
ring.values().removeIf(n -> n.equals(node));
}
public List<String> preferenceList(String key, int n) {
List<String> out = new ArrayList<>();
if (ring.isEmpty()) return out;
long hk = hash(key);
// walk clockwise: tail from hk, then wrap to the head
Iterable<String> walk = () -> {
Iterator<String> a = ring.tailMap(hk, false).values().iterator();
Iterator<String> b = ring.headMap(hk, true).values().iterator();
return new Iterator<>() {
public boolean hasNext() { return a.hasNext() || b.hasNext(); }
public String next() { return a.hasNext() ? a.next() : b.next(); }
};
};
for (String node : walk) {
if (!out.contains(node)) out.add(node);
if (out.size() == n) break;
}
return out;
}
public static void main(String[] args) {
Ring r = new Ring(128);
for (String s : List.of("A", "B", "C", "D", "E")) r.addNode(s);
System.out.println(r.preferenceList("cart:user42", 3));
}
}Lookup is O(log T) for T tokens. Note that the preference list skips repeated physical nodes; without that, two of your three "replicas" could land on the same machine. Production systems also make placement rack/zone aware, choosing the next node in a different availability zone so one zone failure cannot take out all copies. Sharding strategies beyond hashing, such as range partitioning, are compared in database sharding explained.
Deep Dive 2: Replication and the Preference List
Each key is stored on the N nodes of its preference list. The coordinator (normally the first healthy node in that list) does the following for a put:
- Generates a new vector clock version, incrementing its own counter.
- Writes locally.
- Sends the write to the other N−1 replicas in parallel.
- Returns success to the client once W replicas (including itself) have acknowledged.
The remaining replicas keep receiving the write in the background. That is leaderless replication: unlike primary/replica databases, no single node orders all writes for a key. It is why Dynamo stays writable when nodes fail, and also why it needs vector clocks.
Deep Dive 3: Quorums and Tunable Consistency (N, R, W)
N is the replication factor, W is how many acks a write waits for, R is how many replies a read waits for. If R + W > N, every read quorum intersects every write quorum in at least one node, so a read sees at least one replica that holds the latest acknowledged write.
| N, R, W | R + W > N? | Behaviour | Good for |
|---|---|---|---|
| 3, 2, 2 | Yes (4 > 3) | Balanced; tolerates 1 node down for both reads and writes | Default for most data |
| 3, 1, 3 | Yes | Fast reads, writes fail if any replica is down | Read-heavy, rarely written config |
| 3, 3, 1 | Yes | Fast, highly available writes; reads need all replicas | Write-heavy logs with rare reads |
| 3, 1, 1 | No | Lowest latency, may read stale data | Caches, session data, counters you can tolerate being off |
Dry run: why the overlap matters
N = 3, replicas {B, C, D}. A write of v2 reaches B and C (W = 2) while D is slow and still holds v1. A read with R = 2 might ask C and D. It receives v2 from C and v1 from D, sees from the vector clocks that v2 descends from v1, returns v2, and asynchronously writes v2 to D. That last step is read repair. Had we used R = 1 and asked only D, we would have returned stale v1.
Deep Dive 4: Vector Clocks and Conflict Resolution
With leaderless writes, two clients can update the same key through different coordinators at the same time. You need to tell apart "B is a newer version of A" from "A and B were written independently". Wall-clock timestamps cannot do this reliably because clocks skew. A vector clock can.
A vector clock is a map from node ID to counter. When node X coordinates a write, it takes the context the client supplied and increments X's entry. Version A descends from B if every counter in A is ≥ the matching counter in B. If neither descends from the other, they are concurrent and both must be kept as siblings.
Dry run (the shopping-cart example)
| Step | Event | Version and clock |
|---|---|---|
| 1 | Client writes cart via node Sx | D1 {Sx:1} |
| 2 | Same client updates via Sx, passing D1's context | D2 {Sx:2} (descends from D1, D1 can be discarded) |
| 3 | Client 1 updates D2 via Sy | D3 {Sx:2, Sy:1} |
| 4 | Client 2 also read D2 and updates via Sz | D4 {Sx:2, Sz:1} |
| 5 | A read sees D3 and D4 | Neither descends from the other: return both as siblings |
| 6 | Client merges (union of cart items) and writes via Sx with both contexts | D5 {Sx:3, Sy:1, Sz:1} supersedes D3 and D4 |
def descends(a: dict, b: dict) -> bool:
    """True if version with clock a is equal to or newer than clock b."""
    return all(a.get(node, 0) >= cnt for node, cnt in b.items())


def compare(a: dict, b: dict) -> str:
    if descends(a, b) and descends(b, a):
        return "equal"
    if descends(a, b):
        return "a_newer"
    if descends(b, a):
        return "b_newer"
    return "concurrent"


def merge_clocks(*clocks: dict) -> dict:
    out = {}
    for c in clocks:
        for node, cnt in c.items():
            out[node] = max(out.get(node, 0), cnt)
    return out


d3 = {"Sx": 2, "Sy": 1}
d4 = {"Sx": 2, "Sz": 1}
print(compare(d3, d4))                       # concurrent
d5 = merge_clocks(d3, d4); d5["Sx"] += 1
print(d5, compare(d5, d3), compare(d5, d4))  # {'Sx': 3, 'Sy': 1, 'Sz': 1} a_newer a_newer
Vector clocks vs last-write-wins
Cassandra chose the simpler last-write-wins per column using timestamps. It avoids siblings and client merge logic, but concurrent updates silently lose one side, and clock skew can make an older write "win". Riak exposed siblings with vector clocks (later dotted version vectors) or CRDTs. In the interview, present both, and pick based on data: LWW for idempotent overwrites like a user's profile photo URL, siblings or CRDTs for things like carts and counters where merging is meaningful. CRDT merging is explored further in Google Docs: OT vs CRDT.
One practical issue: vector clocks grow with the number of coordinators that touched a key. Dynamo truncated the oldest entries when the clock exceeded about 10 entries, accepting rare false conflicts.
Deep Dive 5: Sloppy Quorum and Hinted Handoff
Suppose key k's preference list is {B, C, D} and D is down. A strict quorum with W = 2 still succeeds via B and C. But with W = 3, or when two replicas are down, strict quorum fails the write. Dynamo instead uses a sloppy quorum: walk further around the ring and use the first healthy nodes, say E.
E stores the write in a separate hints area with metadata "this belongs to D". E periodically checks D's status via gossip; when D returns, E streams the hinted writes to D and deletes them. The write counted toward W even though it was not on a "real" replica.
- Benefit: writes stay available through node failures and short partitions.
- Cost: a read quorum from {B, C, D} may miss the write held on E, so R + W > N no longer guarantees overlap.
- Limit: hints are kept for a bounded window (Cassandra's default
max_hint_windowis 3 hours). After that, a node that was down longer must be fixed by full anti-entropy repair.
Deep Dive 6: Anti-Entropy with Merkle Trees
Hints can be lost if the node holding them dies, and read repair only fixes keys that someone happens to read. To guarantee convergence, replicas periodically compare all their data. Comparing billions of keys naively would ship terabytes, so each node builds a Merkle tree per key range it owns.
- Leaves are hashes of buckets of keys (for example, hash of all key/version pairs whose hash falls in a small sub-range).
- Each parent is the hash of its children. The root summarises the whole range.
- Two replicas exchange roots. Equal roots mean identical data, done. Different roots: exchange the children's hashes and recurse only into mismatching subtrees.
With a tree of depth 15 (32,768 leaves) over a range of 100 million keys, each leaf covers about 3,000 keys. If only 5 keys differ, at most 5 leaves mismatch, and the replicas exchange roughly 15 levels × a few hashes plus 5 small buckets instead of 100 million records. That is the whole point: bandwidth proportional to the difference, not to the data size.
import hashlib


def hsh(b: bytes) -> bytes:
    return hashlib.sha256(b).digest()


def build(leaves: list) -> list:
    """Return tree as list of levels, level[0] = leaf hashes, last = [root]."""
    level = [hsh(x) for x in leaves]
    levels = [level]
    while len(level) > 1:
        if len(level) % 2:
            level = level + [level[-1]]
        level = [hsh(level[i] + level[i + 1]) for i in range(0, len(level), 2)]
        levels.append(level)
    return levels


def diff(a: list, b: list, lvl: int = None, idx: int = 0, out=None) -> list:
    """Indices of leaf buckets that differ; descends only into mismatches."""
    if out is None:
        out, lvl = [], len(a) - 1
    if a[lvl][idx] == b[lvl][idx]:
        return out
    if lvl == 0:
        out.append(idx)
        return out
    for child in (2 * idx, 2 * idx + 1):
        if child < len(a[lvl - 1]):
            diff(a, b, lvl - 1, child, out)
    return out


r1 = [f"bucket{i}".encode() for i in range(8)]
r2 = list(r1); r2[5] = b"bucket5-changed"
print(diff(build(r1), build(r2)))   # [5]
The catch: when a node's ownership changes (a node joins), trees for the affected ranges must be rebuilt, which is expensive. That is one reason later systems fix the set of partitions and move whole partitions between nodes rather than recomputing ranges.
Deep Dive 7: Gossip Membership and Failure Detection
With no master, how does every node learn that node F joined or that D is down? Through gossip: every second, each node picks a random peer (or a few) and exchanges its view of the cluster: member list, each member's heartbeat counter, status and token ownership. Newer heartbeats overwrite older ones.
Information spreads epidemically. In a cluster of n nodes, a change reaches everyone in O(log n) rounds with high probability, so even a 1,000-node cluster converges in a handful of seconds. Per-node network cost stays constant regardless of cluster size, unlike all-to-all heartbeats which are O(n²) in total.
For failure detection, a fixed timeout ("no heartbeat in 5 s means dead") is brittle on noisy networks. Cassandra uses a phi accrual failure detector: it tracks the distribution of heartbeat inter-arrival times per peer and outputs a suspicion level phi; above a threshold (Cassandra's default phi_convict_threshold is 8) the peer is considered down. This adapts to each link's normal jitter.
Important nuance: a node that is "down" in gossip is only temporarily skipped (hinted handoff kicks in). Permanently removing a node or adding a new one is an explicit administrative action, which triggers data streaming to new owners. Dynamo made this explicit because transient failures are far more common than permanent ones, and moving terabytes for a 30-second blip would be wasteful.
Bottlenecks, Deletes and Trade-offs
Deletes and tombstones
You cannot simply remove a key from one replica: anti-entropy would see the other replicas still holding it and "repair" it back. So deletes write a tombstone, a special version that propagates like any write. Compaction removes tombstones only after a grace period (Cassandra's gc_grace_seconds defaults to 10 days), which must be longer than the maximum time a replica can be down without being repaired. Otherwise deleted data resurrects.
Hot keys
Consistent hashing balances keys, not traffic. A celebrity's profile or a flash-sale product can melt three replicas. Mitigations: an application-level cache in front, reading from any replica with R = 1 for that key class, or splitting the key into sub-keys (counter:42#0..15) and summing on read.
Summary of design decisions
| Problem | Technique | Advantage |
|---|---|---|
| Partitioning | Consistent hashing + virtual nodes | Incremental scaling, even load |
| High write availability | Leaderless writes, sloppy quorum | Writes succeed during failures |
| Versioning and conflicts | Vector clocks with client reconciliation | No silent lost updates |
| Temporary failures | Hinted handoff | Availability without immediate data movement |
| Stale replicas on read | Read repair | Cheap repair of hot keys |
| Permanent divergence | Merkle tree anti-entropy | Bandwidth proportional to differences |
| Membership and failure detection | Gossip + phi accrual | Decentralised, scales to large clusters |
The essential trade-off: you bought availability and latency, and paid with application complexity (siblings, merges) and weaker guarantees. If the use case is a bank ledger or a seat inventory, choose a consensus-based store instead (Raft/Paxos per shard), where every write goes through a leader and a majority. Compare this with the simpler leader-per-shard model of a cache in designing a distributed cache.
What Interviewers Probe, and How to Answer
"What if two clients write at once?"
Walk the vector clock dry run. Mention LWW as the alternative and when it is acceptable.
"A node is down for 6 hours"
Hints expire after the window; the node rejoins stale and full Merkle repair runs before it serves reads at full trust.
"Make it strongly consistent"
R = W = N loses availability; the real answer is a leader per partition with Raft. Explain the cost in write latency.
"How do you add a node?"
It takes tokens, streams ranges from current owners while both serve, then ownership flips via gossip. Only ~1/n of data moves.
Common mistakes
- Saying "consistent hashing" without virtual nodes or without explaining replica placement on distinct physical nodes and zones.
- Claiming R + W > N means "strong consistency" with no caveats.
- Using wall-clock timestamps to resolve conflicts and not mentioning clock skew.
- Forgetting tombstones, then being surprised when deleted data comes back.
- Ignoring the single-node storage engine; interviewers often ask "what happens when the write hits the disk?"
- Designing a master node that tracks every key's location. That recreates the bottleneck Dynamo exists to avoid.
If you practise one infrastructure problem deeply, make it this one; the ideas reappear in caches, message queues, object stores and nearly every "design X at scale" question. For a coding-round flavour of the same problem (transactions and TTL in a single process), try the in-memory key-value store LLD.
Frequently Asked Questions
Master System Design Interviews
Prepflix's system design course goes deep on distributed storage, consensus and replication with mock interviews modelled on product company rounds.
Explore the Prepflix Course →